AI Model Distillation ಎಂದರೇನು? ದೊಡ್ಡ AI Models ಅನ್ನು Smaller ಮತ್ತು Faster Models ಆಗಿ ಹೇಗೆ ಮಾಡುತ್ತಾರೆ?
Introduction
ಒಂದು ದೊಡ್ಡ AI model ತುಂಬಾ powerful ಆಗಿರಬಹುದು. ಅದು complex questions ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಹುದು, reasoning ಮಾಡಬಹುದು, images ಅಥವಾ text process ಮಾಡಬಹುದು. ಆದರೆ ಇಂತಹ ದೊಡ್ಡ models ಅನ್ನು run ಮಾಡಲು ಹೆಚ್ಚಿನ computing power, memory ಮತ್ತು energy ಬೇಕಾಗಬಹುದು.
ಹಾಗಾದರೆ ಒಂದು ಪ್ರಶ್ನೆ ಬರುತ್ತದೆ:
ದೊಡ್ಡ AI modelನ knowledge ಮತ್ತು performance ಅನ್ನು smaller modelಗೆ transfer ಮಾಡಬಹುದೇ?
ಹೌದು. Machine Learningನಲ್ಲಿ ಇದಕ್ಕಾಗಿ ಬಳಸುವ ಪ್ರಮುಖ techniqueಗಳಲ್ಲಿ ಒಂದು AI Model Distillation.
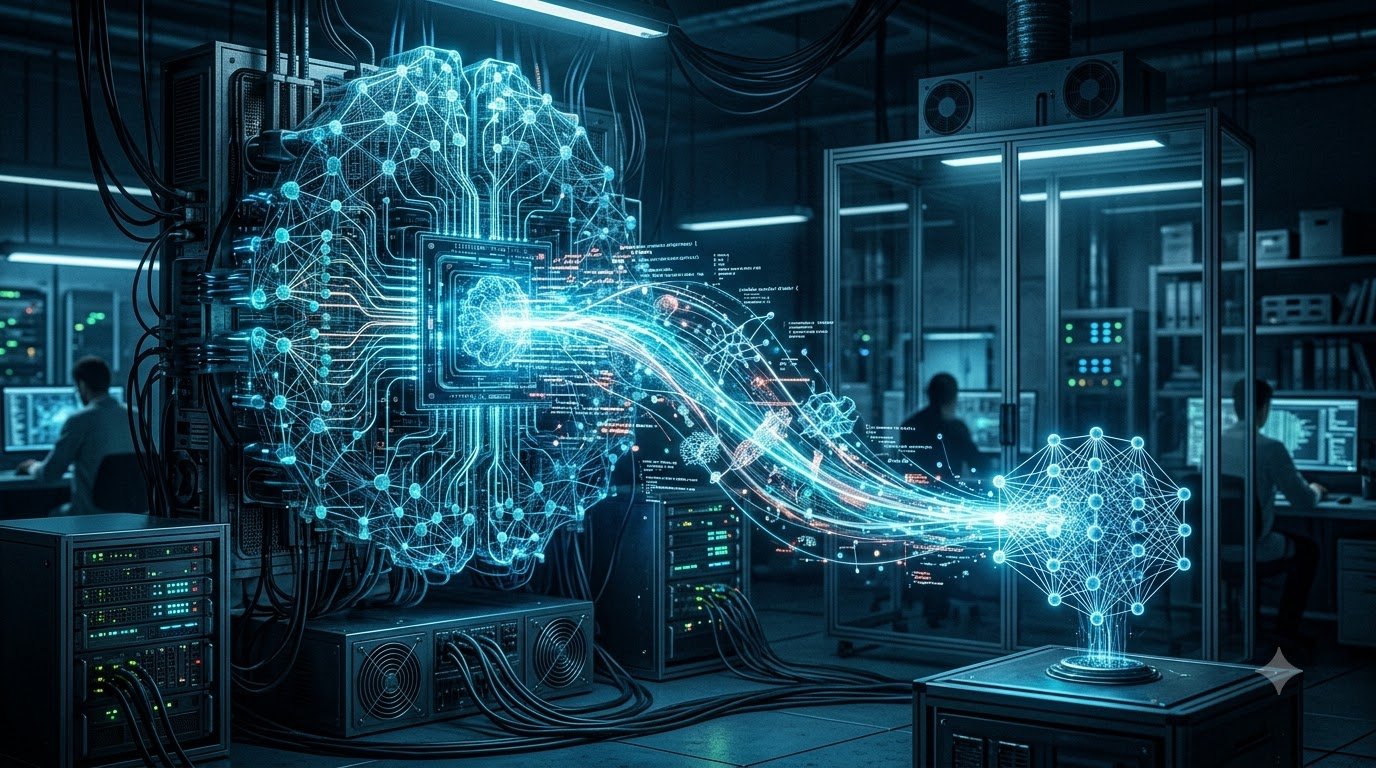
ಸರಳವಾಗಿ ಹೇಳುವುದಾದರೆ, ಒಂದು ದೊಡ್ಡ ಮತ್ತು capable Teacher Model ತನ್ನ learned behaviour ಅಥವಾ useful information ಅನ್ನು ಚಿಕ್ಕ Student Modelಗೆ ಕಲಿಸುತ್ತದೆ.
ಅಂದರೆ:
Large Teacher Model → Knowledge Transfer → Smaller Student Model
ಇದರ ಉದ್ದೇಶ ದೊಡ್ಡ model ಅನ್ನು simply copy ಮಾಡುವುದು ಅಲ್ಲ. ಅದರ useful capabilities ಅನ್ನು smaller modelನಲ್ಲಿ retain ಮಾಡಲು ಪ್ರಯತ್ನಿಸುವುದು.
ಇದರಿಂದ ಕೆಲವು AI applicationsನಲ್ಲಿ model ಅನ್ನು faster, smaller ಮತ್ತು resource-efficient ಆಗಿ deploy ಮಾಡಲು ಸಾಧ್ಯವಾಗಬಹುದು.
Quick Summary
- AI Model Distillation ಎಂದರೆ ದೊಡ್ಡ Teacher Modelನ useful knowledge ಅನ್ನು smaller Student Modelಗೆ transfer ಮಾಡುವ Machine Learning technique.
- Teacher Model ಸಾಮಾನ್ಯವಾಗಿ ಹೆಚ್ಚು capable ಆಗಿರುತ್ತದೆ.
- Student Model ಕಡಿಮೆ parameters ಹೊಂದಿದ್ದರೂ useful behaviour ಕಲಿಯಲು ಪ್ರಯತ್ನಿಸುತ್ತದೆ.
- Distillation ಮೂಲಕ inference speed ಮತ್ತು resource efficiency improve ಮಾಡಬಹುದು.
- Smaller models edge devices, mobile applications ಮತ್ತು resource-constrained environmentsಗೆ useful ಆಗಬಹುದು.
- Distillation ಎಂದರೆ ದೊಡ್ಡ modelನ ಎಲ್ಲಾ capabilities perfectly copy ಆಗುತ್ತವೆ ಎಂದಲ್ಲ.
- Student Modelನ accuracy ಮತ್ತು capabilities teacherಗಿಂತ ಕಡಿಮೆಯಾಗುವ ಸಾಧ್ಯತೆ ಇದೆ.
- Model size ಕಡಿಮೆ ಮಾಡುವುದರ ಜೊತೆಗೆ deployment cost ಮತ್ತು latency ಕೂಡ ಕಡಿಮೆ ಮಾಡುವ ಸಾಧ್ಯತೆ ಇದೆ.
1. AI Model Distillation ಎಂದರೇನು?
AI Model Distillation ಎಂದರೆ ಒಂದು ದೊಡ್ಡ ಮತ್ತು ಹೆಚ್ಚು capable ಆಗಿರುವ Teacher Modelನ useful knowledge, behaviour ಮತ್ತು learned patterns ಅನ್ನು smaller Student Modelಗೆ ಕಲಿಸುವ Machine Learning technique.
ಸರಳವಾಗಿ ಹೇಳುವುದಾದರೆ, ಒಂದು ದೊಡ್ಡ AI model ಅನ್ನು 그대로 copy ಮಾಡುವ ಬದಲು, ಅದು dataನಿಂದ ಕಲಿತಿರುವ useful information ಅನ್ನು ಒಂದು ಚಿಕ್ಕ model ಕಲಿಯುವಂತೆ ಮಾಡುವುದು.
ಇದನ್ನು ಒಬ್ಬ experienced teacher ಮತ್ತು student example ಮೂಲಕ ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಹುದು.
ಒಬ್ಬ expert teacherಗೆ ಒಂದು subject ಬಗ್ಗೆ ತುಂಬಾ knowledge ಇದೆ ಎಂದುಕೊಳ್ಳಿ. ಆ teacher ತನ್ನ ಸಂಪೂರ್ಣ knowledge ಅನ್ನು ಪುಸ್ತಕದ ಪ್ರತಿಯೊಂದು ಪುಟದಂತೆ studentಗೆ copy ಮಾಡಬೇಕಾಗಿಲ್ಲ.
ಬದಲಾಗಿ, ಮುಖ್ಯ concepts, patterns ಮತ್ತು problem-solving methods ಅನ್ನು studentಗೆ ಕಲಿಸಬಹುದು.
AI Model Distillation ಕೂಡ ಇದೇ ರೀತಿಯ idea ಬಳಸುತ್ತದೆ:
Large Teacher Model → Knowledge Transfer → Smaller Student Model
ಇಲ್ಲಿ:
- Teacher Model = ದೊಡ್ಡ ಮತ್ತು ಹೆಚ್ಚು capable AI model
- Student Model = ಚಿಕ್ಕದಾದ ಮತ್ತು resource-efficient AI model
- Knowledge Transfer = Teacherನ learned behaviour ಅನ್ನು Studentಗೆ ಕಲಿಸುವ process
AI Model Distillation ಯಾಕೆ ಬೇಕು?
ಒಂದು ದೊಡ್ಡ AI model powerful ಆಗಿರಬಹುದು. ಆದರೆ ಅದನ್ನು run ಮಾಡಲು:
- ಹೆಚ್ಚು RAM
- ಹೆಚ್ಚು GPU/CPU compute
- ಹೆಚ್ಚು storage
- ಹೆಚ್ಚು energy
- ಹೆಚ್ಚಿನ inference cost
ಬೇಕಾಗಬಹುದು.
ಉದಾಹರಣೆಗೆ ಒಂದು large AI model cloud serverನಲ್ಲಿ powerful hardware ಮೇಲೆ run ಆಗುತ್ತಿದೆ ಎಂದುಕೊಳ್ಳಿ.
ಅದೇ capabilityಯ ಒಂದು useful ಭಾಗವನ್ನು smaller modelನಲ್ಲಿ ಪಡೆಯಲು ಸಾಧ್ಯವಾದರೆ, ಅದನ್ನು:
Mobile Device
Laptop
Edge Device
Enterprise Server
ಮುಂತಾದ environmentsನಲ್ಲಿ ಹೆಚ್ಚು easily deploy ಮಾಡಬಹುದು.
ಇಲ್ಲಿಯೇ AI Model Distillation useful ಆಗುತ್ತದೆ.
PyTorch Knowledge Distillation Tutorial
ಒಂದು Simple Example
ಒಂದು ದೊಡ್ಡ Teacher Model 100% complex model ಎಂದುಕೊಳ್ಳಿ.
ಅದು ಒಂದು image ನೋಡಿ:
“ಇದು ಒಂದು dog.”
ಎಂದು ಮಾತ್ರ ಹೇಳುವುದಿಲ್ಲ.
ಅದರ internal predictionನಲ್ಲಿ:
- Dog → 85%
- Wolf → 8%
- Fox → 5%
- Cat → 2%
ಎಂಬ ರೀತಿಯ probability information ಇರಬಹುದು.
Student Modelಗೆ ಕೇವಲ “Dog” ಎಂದು ಹೇಳುವುದಕ್ಕಿಂತ ಈ richer information ಕೂಡ training signal ಆಗಿ ಸಿಗಬಹುದು.
ಇದರಿಂದ Student Model:
“ಈ image dog ಆಗಿದೆ”
ಎಂಬ final answer ಮಾತ್ರವಲ್ಲದೆ, ಇತರ similar possibilitiesಗಳ ನಡುವಿನ difference ಕೂಡ ಕಲಿಯಲು ಸಾಧ್ಯವಾಗಬಹುದು.
ಇದನ್ನೇ distillationನಲ್ಲಿ soft information ಅಥವಾ soft targets ಎಂದು ಕರೆಯಲಾಗುತ್ತದೆ.
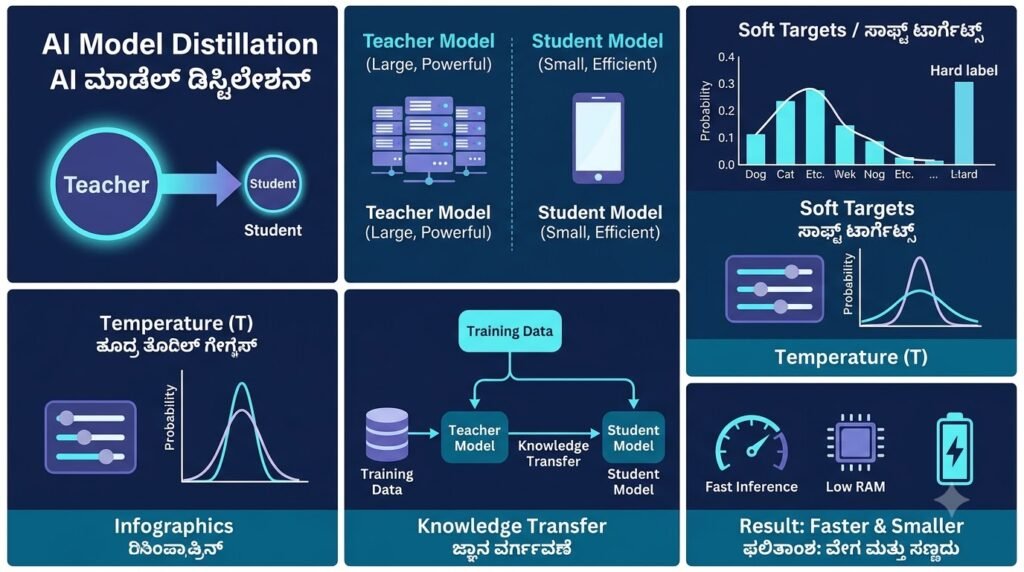
2. Teacher Model ಮತ್ತು Student Model ಅಂದ್ರೆ ಏನು?
AI Model Distillation ಅರ್ಥಮಾಡಿಕೊಳ್ಳಲು ಮೊದಲು Teacher Model ಮತ್ತು Student Model roles clear ಆಗಬೇಕು.
Teacher Model ಎಂದರೇನು?
Teacher Model ಸಾಮಾನ್ಯವಾಗಿ ದೊಡ್ಡ, ಹೆಚ್ಚು capable ಮತ್ತು already trained ಆಗಿರುವ AI model.
ಇದು ದೊಡ್ಡ dataset ಮೇಲೆ train ಆಗಿರಬಹುದು ಮತ್ತು complex patterns ಕಲಿತಿರಬಹುದು.
ಉದಾಹರಣೆಗೆ Teacher Model:
- ಹೆಚ್ಚು parameters ಹೊಂದಿರಬಹುದು
- complex patterns capture ಮಾಡಬಹುದು
- ಉತ್ತಮ accuracy ನೀಡಬಹುದು
- ಹೆಚ್ಚು computational resources ಬಳಸಬಹುದು
ಅದರ role:
Student Modelಗೆ useful knowledge ಕಲಿಸುವುದು.
Teacher Model ಅನ್ನು ಸಾಮಾನ್ಯವಾಗಿ ಹೊಸ taskನಲ್ಲಿ zeroದಿಂದ train ಮಾಡುವುದಕ್ಕಿಂತ, already trained modelನ knowledge ಅನ್ನು Studentಗೆ transfer ಮಾಡಲು ಬಳಸಲಾಗುತ್ತದೆ.
PyTorch — Distilling Llama 3.1 8B into Llama 3.2 1B
Student Model ಎಂದರೇನು?
Student Model Teacherಗಿಂತ smaller model.
ಇದರ goal:
Teacher Modelನ useful capabilities ಅನ್ನು ಕಡಿಮೆ parameters ಮತ್ತು ಕಡಿಮೆ computational requirementsನಲ್ಲಿ ಕಲಿಯುವುದು.
Student Model:
- smaller ಆಗಿರಬಹುದು
- faster ಆಗಿರಬಹುದು
- ಕಡಿಮೆ memory ಬಳಸಬಹುದು
- deploymentಗೆ easier ಆಗಿರಬಹುದು
ಆದರೆ ಒಂದು important point:
Student Model ಯಾವಾಗಲೂ Teacher Modelನ performance ಅನ್ನು 100% match ಮಾಡುತ್ತದೆ ಎಂದು guarantee ಇಲ್ಲ.
Distillationನ goal ಸಾಮಾನ್ಯವಾಗಿ useful performance ಅನ್ನು retain ಮಾಡುತ್ತಾ model ಅನ್ನು more efficient ಮಾಡುವುದು.
Reasoning AI Models Explained: How They Think Before They Answer
Teacher vs Student — Simple Comparison
| Feature | Teacher Model | Student Model |
|---|---|---|
| Model Size | ಸಾಮಾನ್ಯವಾಗಿ ದೊಡ್ಡದು | ಸಾಮಾನ್ಯವಾಗಿ ಚಿಕ್ಕದು |
| Capability | ಹೆಚ್ಚು complex | comparatively ಕಡಿಮೆ |
| Compute Requirement | ಹೆಚ್ಚು | ಕಡಿಮೆ |
| Memory | ಹೆಚ್ಚು ಬೇಕಾಗಬಹುದು | ಕಡಿಮೆ ಬೇಕಾಗಬಹುದು |
| Speed | ಕೆಲವೊಮ್ಮೆ slower | ಸಾಮಾನ್ಯವಾಗಿ faster |
| Main Role | Knowledge ನೀಡುವುದು | Knowledge ಕಲಿಯುವುದು |
| Deployment | Powerful hardware ಬೇಕಾಗಬಹುದು | More environmentsನಲ್ಲಿ deploy ಮಾಡಬಹುದು |
ಅಂದರೆ:
Teacher = Expert
Student = Efficient Learner
3. AI Model Distillation ಹೇಗೆ ಕೆಲಸ ಮಾಡುತ್ತದೆ?
ಈಗ actual AI Model Distillation process ಅನ್ನು step-by-step ನೋಡೋಣ.
ಇದು simply:
Big Model → Small Model
ಅಷ್ಟೇ ಅಲ್ಲ.
Teacher Modelನ output ಅನ್ನು ಬಳಸಿಕೊಂಡು Student Modelಗೆ training ನೀಡಲಾಗುತ್ತದೆ.
Step 1: Teacher Model Train ಮಾಡುವುದು
ಮೊದಲಿಗೆ ಒಂದು capable Teacher Model ಅನ್ನು ದೊಡ್ಡ dataset ಮೇಲೆ train ಮಾಡಲಾಗುತ್ತದೆ.
ಈ model:
Input → Prediction
ಮಾಡುವಾಗ dataನಲ್ಲಿರುವ complex relationships ಮತ್ತು patterns ಕಲಿಯುತ್ತದೆ.
Step 2: Teacher Modelಗೆ Input Data ಕೊಡುವುದು
ನಂತರ training examples ಅನ್ನು Teacher Modelಗೆ pass ಮಾಡಲಾಗುತ್ತದೆ.
ಉದಾಹರಣೆಗೆ image classification taskನಲ್ಲಿ:
Image → Teacher Model
Teacher Model ಅದನ್ನು process ಮಾಡುತ್ತದೆ.
Step 3: Teacher Predictions Generate ಮಾಡುವುದು
Teacher Model final answer ಜೊತೆಗೆ probability information ಕೂಡ generate ಮಾಡಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Image: Animal
Teacher output:
- Dog — 0.82
- Wolf — 0.10
- Fox — 0.06
- Cat — 0.02
ಇಲ್ಲಿ Studentಗೆ Dog = correct answer ಎಂಬ information ಮಾತ್ರ ಸಿಗುತ್ತಿಲ್ಲ.
ಇತರ classes ಜೊತೆ ಅದರ similarity ಅಥವಾ uncertainty ಬಗ್ಗೆ ಕೂಡ signal ಸಿಗುತ್ತದೆ.
Step 4: Student Model Training
ಈಗ ಅದೇ input ಅನ್ನು Student Modelಗೆ ಕೊಡಲಾಗುತ್ತದೆ.
Student:
Image → Student Model → Prediction
ಮಾಡುತ್ತದೆ.
Training ಸಮಯದಲ್ಲಿ Studentನ output ಅನ್ನು Teacherನ output ಜೊತೆ compare ಮಾಡಲಾಗುತ್ತದೆ.
Goal:
Student Model ತನ್ನ predictions ಅನ್ನು Teacher Modelನ useful behaviourಗೆ ಹತ್ತಿರ ತರಬೇಕು.
Step 5: Distillation Loss
Teacher ಮತ್ತು Student predictions ನಡುವಿನ difference ಅನ್ನು measure ಮಾಡಲು Distillation Loss ಬಳಸಬಹುದು.
Trainingನಲ್ಲಿ Student model:
Teacher Output + Original Labels
ಎರಡರಿಂದ learning ಪಡೆಯಬಹುದು.
ಅಂದರೆ simplified workflow:
Input Data
↓
Teacher Model
↓
Teacher Prediction / Soft Targets
↓
Student Model
↓
Compare Outputs
↓
Distillation Loss
↓
Update Student
ಈ process repeated ಆಗುತ್ತಾ Student Model gradually improve ಆಗುತ್ತದೆ.
Hinton, Vinyals & Dean — Distilling the Knowledge in a Neural Network
The Ultimate Guide to How AI Agents Work: Memory, Planning, Tools and Real-World Examples
4. Hard Labels ಮತ್ತು Soft Labels ಎಂದರೇನು?
ಇದು AI Model Distillationನಲ್ಲಿ ಬಹಳ important concept.
Hard Label ಎಂದರೇನು?
ಒಂದು classification example ತೆಗೆದುಕೊಳ್ಳೋಣ.
Image ಒಂದು dog ಆಗಿದ್ದರೆ:
Dog = 1
Cat = 0
Wolf = 0
ಇದು hard label.
ಅಂದರೆ correct class ಯಾವುದು ಎಂಬುದು direct ಆಗಿ ಹೇಳಲಾಗುತ್ತದೆ.
Soft Label ಎಂದರೇನು?
Teacher Model ಹೆಚ್ಚು detailed prediction ನೀಡಬಹುದು:
Dog = 82%
Wolf = 10%
Fox = 6%
Cat = 2%
ಇದು soft target information.
ಇಲ್ಲಿ Studentಗೆ:
“Correct answer dog.”
ಎಂಬುದು ಮಾತ್ರವಲ್ಲದೆ,
“ಈ image wolf ಮತ್ತು fox ಜೊತೆ ಸ್ವಲ್ಪ similarity ಹೊಂದಿದೆ, ಆದರೆ dogಗೆ ಹೆಚ್ಚು confidence ಇದೆ.”
ಎಂಬ richer signal ಸಿಗಬಹುದು.
ಇದರಿಂದ Student Modelಗೆ dataನ relationships ಬಗ್ಗೆ additional information ಸಿಗುತ್ತದೆ.
PyTorch — Llama Knowledge Distillation Guide
5. Soft Targets ಯಾಕೆ Important?
Normal trainingನಲ್ಲಿ Studentಗೆ correct answer ಮಾತ್ರ ನೀಡಿದರೆ, ಅದು final label ಕಲಿಯುತ್ತದೆ.
ಆದರೆ Teacher Modelನ soft output ಬಳಸಿದಾಗ Studentಗೆ predictions ನಡುವಿನ relative relationships ಬಗ್ಗೆ ಹೆಚ್ಚು information ಸಿಗಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Hard Label
Dog = 1
ಇತರ ಎಲ್ಲಾ classes:
0
Studentಗೆ simple signal ಸಿಗುತ್ತದೆ.
Soft Target
Dog = 0.82
Wolf = 0.10
Fox = 0.06
Cat = 0.02
ಇಲ್ಲಿ Studentಗೆ ಹೆಚ್ಚು nuanced information ಸಿಗುತ್ತದೆ.
ಇದನ್ನು ಒಂದು classroom example ಮೂಲಕ ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಹುದು.
Teacher:
“ಈ answer correct.”
ಎಂದು ಹೇಳುವುದಕ್ಕಿಂತ,
“ಈ answer correct, ಆದರೆ ಈ ಎರಡು options ಕೂಡ somewhat similar; ಈ ಕಾರಣಕ್ಕೆ correct answerಗೆ higher confidence ಇದೆ.”
ಎಂದು explain ಮಾಡಿದರೆ studentಗೆ concept ಬಗ್ಗೆ ಹೆಚ್ಚು information ಸಿಗುತ್ತದೆ.
Distillationನಲ್ಲಿ Teacher Modelನ output ಇದೇ ರೀತಿಯ additional learning signal ಆಗಿ ಕೆಲಸ ಮಾಡಬಹುದು.
6. Temperature ಎಂದರೇನು?
Temperature ಎಂಬ concept distillation trainingನಲ್ಲಿ soft targets ಅನ್ನು control ಮಾಡಲು ಬಳಸಲಾಗುತ್ತದೆ.
ಇದನ್ನು beginner levelನಲ್ಲಿ simple ಆಗಿ ನೋಡೋಣ.
Teacher Model ಸಾಮಾನ್ಯವಾಗಿ ಒಂದು classಗೆ ತುಂಬಾ high probability ನೀಡಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Dog = 95%
Wolf = 3%
Fox = 1%
Cat = 1%
ಇದು Studentಗೆ relatively sharp signal.
Temperature ಹೆಚ್ಚಿಸಿದಾಗ probability distribution ಹೆಚ್ಚು soft ಆಗಬಹುದು.
ಉದಾಹರಣೆಗೆ conceptually:
Dog = 65%
Wolf = 20%
Fox = 10%
Cat = 5%
ಹೀಗೆ smaller differences ಹೆಚ್ಚು visible ಆಗಬಹುದು.
ಇದರಿಂದ Student Modelಗೆ Teacherನ predictionsನಲ್ಲಿರುವ relationships ಬಗ್ಗೆ richer signal ಸಿಗಬಹುದು.
Temperature ಯಾಕೆ ಬಳಸುತ್ತಾರೆ?
ಮುಖ್ಯ idea:
Teacher Modelನ outputನಲ್ಲಿ hidden relationships ಅನ್ನು Studentಗೆ ಹೆಚ್ಚು useful learning signal ಆಗಿ ನೀಡುವುದು.
ಅದರ ಮೂಲಕ Student Model Teacherನ behaviour ಅನ್ನು better approximate ಮಾಡಲು ಪ್ರಯತ್ನಿಸುತ್ತದೆ.
7. Large AI Modelನ Knowledge ಅನ್ನು Small Modelಗೆ ಹೇಗೆ Transfer ಮಾಡುತ್ತಾರೆ?
ಈಗ ಸಂಪೂರ್ಣ process ಅನ್ನು ಒಂದು practical pipelineನಲ್ಲಿ ನೋಡೋಣ.
Stage 1 — Teacher
ಒಂದು large pretrained model select ಮಾಡಲಾಗುತ್ತದೆ.
Large Dataset → Teacher Model
Teacher ತನ್ನ learned patterns ಮತ್ತು representations ಹೊಂದಿರುತ್ತದೆ.
Stage 2 — Generate Teacher Outputs
Training data ಅನ್ನು Teacher Model ಮೂಲಕ pass ಮಾಡಲಾಗುತ್ತದೆ.
Input → Teacher → Soft Targets
Stage 3 — Train Student
ಅದೇ input Student Modelಗೆ ನೀಡಲಾಗುತ್ತದೆ.
Input → Student → Student Prediction
Stage 4 — Compare
Student prediction ಅನ್ನು Teacher output ಮತ್ತು ground-truth label ಜೊತೆ compare ಮಾಡಲಾಗುತ್ತದೆ.
Stage 5 — Optimize
Training algorithm Student Modelನ parameters update ಮಾಡುತ್ತದೆ.
Goal:
Student Output ≈ Teacher’s Useful Behaviour
Stage 6 — Evaluate
Training ಮುಗಿದ ನಂತರ Student Model ಅನ್ನು independent evaluation datasets ಮೇಲೆ test ಮಾಡಲಾಗುತ್ತದೆ.
ಅಲ್ಲಿ:
- accuracy
- latency
- memory usage
- model size
- inference cost
ಮುಂತಾದ factors ನೋಡಬಹುದು.
ಅಂದರೆ successful distillation ಎಂದರೆ ಕೇವಲ “student model smaller ಆಯಿತು” ಎಂದಲ್ಲ.
Smaller + Useful Performance + Efficient Inference
ಮೂರೂ important.
8. AI Model Distillation ಯಾಕೆ Important?
ಇಂದಿನ AI models increasingly ದೊಡ್ಡದಾಗುತ್ತಿವೆ.
More parameters ಮತ್ತು complex architectures ಉತ್ತಮ capabilities ನೀಡಬಹುದು. ಆದರೆ model ದೊಡ್ಡದಾದಂತೆ deployment ಕೂಡ difficult ಆಗಬಹುದು.
ಇಲ್ಲಿ AI Model Distillation ಒಂದು efficiency technique ಆಗಿ useful.
Faster Inference
Smaller Student Model less computation ಬೇಕಾಗಬಹುದು.
ಅದರ ಪರಿಣಾಮವಾಗಿ ಕೆಲವು applicationsನಲ್ಲಿ response latency ಕಡಿಮೆಯಾಗಬಹುದು.
Lower Memory Requirement
Small modelಗೆ ದೊಡ್ಡ modelಗಿಂತ ಕಡಿಮೆ memory ಬೇಕಾಗಬಹುದು.
ಇದು mobile ಮತ್ತು edge devicesಗೆ useful.
Lower Computing Cost
Cloud inferenceನಲ್ಲಿ compute usage ಕಡಿಮೆಯಾದರೆ operational cost ಕೂಡ ಕಡಿಮೆಯಾಗುವ ಸಾಧ್ಯತೆ ಇದೆ.
Easier Deployment
ಒಂದು huge model run ಮಾಡಲು powerful GPU infrastructure ಬೇಕಾಗಬಹುದು.
Smaller model ಅನ್ನು comparatively modest hardwareನಲ್ಲಿ deploy ಮಾಡುವ ಅವಕಾಶ ಇರಬಹುದು.
Edge AIಗೆ Useful
AI processing deviceನಲ್ಲೇ ಮಾಡಬೇಕಾದ ಸಂದರ್ಭಗಳಲ್ಲಿ model size ಮತ್ತು efficiency ಬಹಳ important.
ಉದಾಹರಣೆಗೆ:
Camera → Local AI Model → Instant Detection
ಇಂತಹ applicationsನಲ್ಲಿ small models practical ಆಗಬಹುದು.
9. AI Model Distillation ಮತ್ತು Model Compression ಒಂದೇನಾ?
ಇವೆರಡೂ related concepts ಆದರೆ exactly same ಅಲ್ಲ.
Model Compression
Modelನ size ಅಥವಾ computational requirements ಕಡಿಮೆ ಮಾಡುವ broad category.
ಇದರಲ್ಲಿ ಹಲವು techniques ಇರಬಹುದು:
- Quantization
- Pruning
- Weight sharing
- Knowledge distillation
Knowledge Distillation
Teacher Modelನ knowledge ಬಳಸಿಕೊಂಡು Student Modelಗೆ training ನೀಡುವ specific technique.
ಅಂದರೆ:
Model Compression = ದೊಡ್ಡ umbrella
Knowledge Distillation = ಆ umbrella ಒಳಗಿನ ಒಂದು ಪ್ರಮುಖ technique
ಇದನ್ನು simple ಆಗಿ:
Compression = Model ಅನ್ನು smaller/efficient ಮಾಡುವುದು
Distillation = Teacherನ knowledge ಬಳಸಿ Studentಗೆ ಕಲಿಸುವುದು
ಎಂದು ನೆನಪಿಟ್ಟುಕೊಳ್ಳಬಹುದು.
Multimodal AI ಅಂದ್ರೆ ಏನು? Text + Image + Audio AI Systems ಹೇಗೆ ಕೆಲಸ ಮಾಡುತ್ತವೆ? (2026 Guide)
NVIDIA — Pruning and Distilling LLMs Using TensorRT Model Optimizer
10. AI Model Distillationನ Advantages
AI Model Distillation ಬಳಸುವುದರಿಂದ ಹಲವು practical advantages ಸಿಗಬಹುದು.
1. Smaller Model
Student Model Teacherಗಿಂತ significantly smaller ಆಗಿರಬಹುದು.
2. Faster Response
ಕಡಿಮೆ computation ಬೇಕಾದರೆ inference speed improve ಆಗಬಹುದು.
3. Lower Resource Usage
CPU, GPU ಮತ್ತು memory requirements ಕಡಿಮೆಯಾಗುವ ಸಾಧ್ಯತೆ ಇದೆ.
4. Mobile Deployment
Small model mobile ಅಥವಾ edge hardwareನಲ್ಲಿ run ಮಾಡಲು ಹೆಚ್ಚು practical ಆಗಬಹುದು.
5. Cost Efficiency
Large-scale AI deploymentನಲ್ಲಿ inference cost ಕಡಿಮೆ ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
6. Specialized AI
ಒಂದು general-purpose Teacher Modelನ useful capability ಅನ್ನು specific taskಗಾಗಿ smaller Student Modelನಲ್ಲಿ transfer ಮಾಡಬಹುದು.
ಇದರಿಂದ:
General Large Model → Specialized Small Model
ಎಂಬ approach ಸಾಧ್ಯವಾಗಬಹುದು.
Top AI Productivity Tools Review: Daily Work Faster ಮಾಡಲು Powerful AI Tools (2026)
NVIDIA — Efficient AI with Knowledge Distillation
11. AI Model Distillationನ Limitations ಮತ್ತು Challenges
AI Model Distillation useful technique ಆಗಿದ್ದರೂ, ಇದು ಒಂದು magic solution ಅಲ್ಲ.
ದೊಡ್ಡ Teacher Modelನ knowledge ಅನ್ನು smaller Student Modelಗೆ transfer ಮಾಡಿದಾಗ ಕೆಲವು information ಮತ್ತು capabilities loss ಆಗುವ ಸಾಧ್ಯತೆ ಇದೆ.
ಅಂದರೆ:
Large Model → Distillation → Small Model
ಎಂದರೆ:
100% same model → smaller size
ಎಂದು ಅರ್ಥವಲ್ಲ.
Student Modelನಲ್ಲಿ ಕೆಲವು trade-offs ಇರಬಹುದು.
1. Knowledge Loss
Teacher Model ಬಹಳ ದೊಡ್ಡ ಮತ್ತು complex ಆಗಿದ್ದರೆ, ಅದರ ಎಲ್ಲಾ knowledge ಮತ್ತು behaviours ಅನ್ನು smaller Student Modelನಲ್ಲಿ retain ಮಾಡುವುದು difficult.
Student Modelನ capacity ಕಡಿಮೆಯಿರುವುದರಿಂದ ಕೆಲವು complex patterns ಅಥವಾ less-common knowledge miss ಆಗಬಹುದು.
2. Accuracy ಕಡಿಮೆಯಾಗಬಹುದು
ಕೆಲವು tasksನಲ್ಲಿ Student Model Teacher Modelನ performance ಅನ್ನು match ಮಾಡದೇ ಇರಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Teacher Accuracy → 95%
Student Accuracy → 91%
ಆಗ model size ಮತ್ತು efficiency improve ಆಗಿರಬಹುದು, ಆದರೆ ಕೆಲವು accuracy trade-off ಬಂದಿದೆ.
ಆದ್ದರಿಂದ distillationನಲ್ಲಿ question ಕೇವಲ:
“Model ಎಷ್ಟು ಚಿಕ್ಕದಾಯಿತು?”
ಎಂಬುದಲ್ಲ.
ಅದರ ಜೊತೆಗೆ:
“ಎಷ್ಟು performance retain ಮಾಡಲಾಗಿದೆ?”
ಎಂಬುದೂ ಮುಖ್ಯ.
3. Teacher Model Quality ಮುಖ್ಯ
Student Model ಎಷ್ಟು ಚೆನ್ನಾಗಿ ಕಲಿಯುತ್ತದೆ ಎಂಬುದು Teacher Modelನ quality ಮೇಲೂ depend ಆಗುತ್ತದೆ.
Teacher ತಪ್ಪಾದ ಅಥವಾ biased outputs ನೀಡಿದರೆ, Student ಕೂಡ ಅವುಗಳಿಂದ learning ಪಡೆಯಬಹುದು.
ಅಂದರೆ:
Bad Teacher Signal → Bad Student Learning
ಎಂಬ ಸಮಸ್ಯೆ ಬರಬಹುದು.
4. Training ಇನ್ನೂ Compute ಬೇಕಾಗುತ್ತದೆ
Student Model final deploymentನಲ್ಲಿ efficient ಆಗಿರಬಹುದು.
ಆದರೆ distillation training ಮಾಡುವ ಸಮಯದಲ್ಲಿ Teacher Model ಅನ್ನು run ಮಾಡಬೇಕಾಗಬಹುದು.
ಅದರಿಂದ initial training processಗೆ significant computing resources ಬೇಕಾಗಬಹುದು.
ಅಂದರೆ:
Deployment Cost ↓
ಆದರೆ
Training Cost ≠ Zero
ಎಂಬುದನ್ನು ನೆನಪಿಟ್ಟುಕೊಳ್ಳಬೇಕು.
5. ಎಲ್ಲಾ Modelsಗೆ ಒಂದೇ Distillation Strategy ಕೆಲಸ ಮಾಡುವುದಿಲ್ಲ
Text AI, Vision AI, Speech AI ಮತ್ತು Multimodal AI models ವಿಭಿನ್ನ ರೀತಿಯಲ್ಲಿ ಕೆಲಸ ಮಾಡುತ್ತವೆ.
ಆದ್ದರಿಂದ ಒಂದು modelಗೆ successful ಆಗಿರುವ distillation method ಅನ್ನು ಮತ್ತೊಂದು modelಗೆ As it is apply ಮಾಡಿದರೆ same result ಸಿಗುತ್ತದೆ ಎಂದು ಹೇಳಲಾಗುವುದಿಲ್ಲ.
AI Safety Debate: 5 Serious Autonomous AI Agent Security Incidents You Should Know
Knowledge Distillation: A Survey
12. Real-World Applicationsನಲ್ಲಿ AI Model Distillation ಹೇಗೆ ಉಪಯೋಗವಾಗಬಹುದು?
ಈಗ theoryಯಿಂದ practical worldಗೆ ಬರೋಣ.
AI Model Distillationನ ದೊಡ್ಡ advantage ಎಂದರೆ large AI capabilityಯ ಕೆಲವು useful parts ಅನ್ನು smaller modelsಗೆ ತರಲು ಸಾಧ್ಯವಾಗುವುದು.
ಇದು particularly resource-constrained environmentsನಲ್ಲಿ useful ಆಗಬಹುದು.
Mobile AI
Smartphoneನಲ್ಲಿ AI features ಹೆಚ್ಚಾಗುತ್ತಿವೆ.
ಆದರೆ phoneನಲ್ಲಿ massive cloud-scale AI model run ಮಾಡುವುದು ಯಾವಾಗಲೂ practical ಆಗುವುದಿಲ್ಲ.
ಅದಕ್ಕಾಗಿ smaller distilled model ಬಳಸಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Camera → Small AI Model → Image Analysis
ಇಲ್ಲಿ model deviceನಲ್ಲೇ locally run ಆಗುವ ಸಾಧ್ಯತೆ ಇರುತ್ತದೆ.
ಇದರಿಂದ ಕೆಲವು applicationsನಲ್ಲಿ:
- faster response
- lower latency
- reduced cloud dependency
ಸಿಗಬಹುದು.
Edge AI
Edge AI ಎಂದರೆ data generate ಆಗುವ device ಅಥವಾ ಅದರ ಹತ್ತಿರವೇ AI processing ಮಾಡುವ approach.
ಉದಾಹರಣೆಗೆ:
- security cameras
- industrial sensors
- smart machines
- IoT devices
- robotics
ಇವುಗಳಲ್ಲಿ large model deploy ಮಾಡುವುದು difficult ಆಗಬಹುದು.
Smaller distilled model ಇಲ್ಲಿ ಹೆಚ್ಚು practical ಆಗಬಹುದು.
Example
ಒಂದು factory camera continuously products inspect ಮಾಡುತ್ತಿದೆ ಎಂದುಕೊಳ್ಳಿ.
Camera → Edge Device → Small AI Model → Defect Detection
ಪ್ರತಿಯೊಂದು image ಅನ್ನು cloudಗೆ upload ಮಾಡುವ ಬದಲು deviceನಲ್ಲೇ initial AI analysis ಮಾಡಬಹುದು.
ಇದು ಕೆಲವು situationsನಲ್ಲಿ latency ಮತ್ತು bandwidth usage ಕಡಿಮೆ ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
13. Enterprise AIನಲ್ಲಿ Distillation ಯಾಕೆ Useful?
ಒಂದು company ದೊಡ್ಡ AI model ಅನ್ನು internal applicationsನಲ್ಲಿ ಬಳಸುತ್ತಿದೆ ಎಂದುಕೊಳ್ಳಿ.
ಪ್ರತಿದಿನ ಸಾವಿರಾರು ಅಥವಾ ಲಕ್ಷಾಂತರ AI requests ಬಂದರೆ inference cost ದೊಡ್ಡ operational factor ಆಗಬಹುದು.
ಇಲ್ಲಿ company ಒಂದು capable Teacher Model ಬಳಸಿ ತನ್ನ specific business taskಗಾಗಿ smaller Student Model train ಮಾಡಬಹುದು.
Example
ಒಂದು companyಗೆ customer-support AI ಬೇಕಾಗಿದೆ.
Teacher Model:
Large General AI
Student Model:
Smaller Customer-Support AI
Studentಗೆ companyಯ specific support patterns ಮತ್ತು response behaviour ಕಲಿಸಬಹುದು.
ನಂತರ repetitive customer-support tasksಗೆ smaller model deploy ಮಾಡಬಹುದು.
ಇದರಿಂದ large modelನ ಎಲ್ಲಾ capabilities ಪ್ರತಿಯೊಂದು requestಗೂ ಬಳಸಬೇಕಾಗಿಲ್ಲ.
14. Large AI Model vs Distilled Small AI Model
ಒಂದು simple comparison ಮಾಡೋಣ.
| Feature | Large AI Model | Distilled Small Model |
|---|---|---|
| Size | ಸಾಮಾನ್ಯವಾಗಿ ದೊಡ್ಡದು | ಚಿಕ್ಕದು |
| Compute | ಹೆಚ್ಚು | ಕಡಿಮೆ |
| Memory | ಹೆಚ್ಚು | ಕಡಿಮೆ |
| Inference | comparatively heavy | ಸಾಮಾನ್ಯವಾಗಿ faster |
| Capability | ಹೆಚ್ಚು broad | ಹೆಚ್ಚು focused ಆಗಿರಬಹುದು |
| Deployment | powerful infrastructure ಬೇಕಾಗಬಹುದು | ಹೆಚ್ಚು environmentsನಲ್ಲಿ deploy ಮಾಡಬಹುದು |
| Cost | ಹೆಚ್ಚು ಇರಬಹುದು | ಕಡಿಮೆ ಮಾಡುವ ಸಾಧ್ಯತೆ |
| Best Use | Complex/general tasks | Specific/efficient tasks |
ಇಲ್ಲಿ “Small = Always Better” ಎಂದು ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಾರದು.
ಒಂದು highly complex reasoning taskಗೆ large model ಇನ್ನೂ better fit ಆಗಬಹುದು.
ಆದರೆ simple ಮತ್ತು repetitive taskಗೆ smaller distilled model ಸಾಕಾಗಬಹುದು.
ಹೀಗಾಗಿ real-world AI architectureನಲ್ಲಿ ಎರಡೂ ಇರಬಹುದು:
Large Model → Complex Tasks
Small Model → Routine Tasks
15. AI Model Distillation ಮತ್ತು Edge AI ಯಾಕೆ Strong Combination?
Edge deviceನಲ್ಲಿ ಮೂರು ಪ್ರಮುಖ constraints ಇರುತ್ತವೆ:
Compute
Memory
Power
ಒಂದು large AI model ಈ resources ಅನ್ನು ಹೆಚ್ಚು ಬಳಸಿದರೆ deviceನಲ್ಲಿ deployment difficult ಆಗಬಹುದು.
Distillation ಮೂಲಕ smaller model ಸಿಕ್ಕರೆ:
Smaller Model → Less Computation → Potentially Lower Resource Usage
ಎಂಬ advantage ಸಿಗಬಹುದು.
Battery-powered devicesನಲ್ಲಿ ಇದು particularly useful ಆಗಬಹುದು.
ಉದಾಹರಣೆಗೆ ಒಂದು smart camera continuously AI inference ಮಾಡಬೇಕಾದರೆ, compact model practical advantage ನೀಡಬಹುದು.
AI Agents 2026 Breakthrough: How Autonomous AI Systems Are Changing Work, Business and Daily Life
16. AI Model Distillation ಮತ್ತು Privacy
Distillation ಸ್ವತಃ privacy technology ಅಲ್ಲ.
ಆದರೆ smaller models ಅನ್ನು on-device AI applicationsನಲ್ಲಿ deploy ಮಾಡುವ ಸಾಧ್ಯತೆ ಹೆಚ್ಚಿರುವುದರಿಂದ, ಕೆಲವು use casesನಲ್ಲಿ data processing local ಆಗಿ ಇಡಲು ಇದು supporting role ವಹಿಸಬಹುದು.
ಉದಾಹರಣೆಗೆ:
User Data → Device → Local AI Model
ಎಂಬ architecture ಇದ್ದರೆ, every input ಅನ್ನು cloud serverಗೆ ಕಳುಹಿಸುವ ಅಗತ್ಯ ಕೆಲವು applicationsನಲ್ಲಿ ಕಡಿಮೆಯಾಗಬಹುದು.
ಆದರೆ ಇದು automatically privacy guarantee ಮಾಡುವುದಿಲ್ಲ.
Application ಹೇಗೆ designed ಆಗಿದೆ, data ಎಲ್ಲಿ store ಆಗುತ್ತದೆ ಮತ್ತು networkಗೆ ಏನು ಕಳುಹಿಸಲಾಗುತ್ತದೆ ಎಂಬುದು equally important.
17. AI Model Distillationನಲ್ಲಿ Performance ಹೇಗೆ Measure ಮಾಡಬೇಕು?
ಒಂದು distilled model successful ಆಗಿದೆಯೇ ಎಂದು model size ಮಾತ್ರ ನೋಡಿ ನಿರ್ಧರಿಸಬಾರದು.
ಹಲವು metrics consider ಮಾಡಬೇಕು.
Accuracy
Student Model original taskನಲ್ಲಿ ಎಷ್ಟು correct results ನೀಡುತ್ತದೆ?
Latency
ಒಂದು input process ಮಾಡಲು ಎಷ್ಟು ಸಮಯ ತೆಗೆದುಕೊಳ್ಳುತ್ತದೆ?
Memory Usage
Model run ಮಾಡಲು ಎಷ್ಟು RAM ಅಥವಾ accelerator memory ಬೇಕಾಗುತ್ತದೆ?
Model Size
Storageನಲ್ಲಿ model ಎಷ್ಟು space ತೆಗೆದುಕೊಳ್ಳುತ್ತದೆ?
Compute Cost
Inferenceಗೆ ಎಷ್ಟು computational resources ಬೇಕಾಗುತ್ತವೆ?
Quality Retention
Teacher Modelನ useful capabilitiesನಲ್ಲಿ ಎಷ್ಟು ಭಾಗ Student retain ಮಾಡಿದೆ?
ಒಂದು useful evaluation idea:
Efficiency Gain + Acceptable Quality
ಇವೆರಡೂ balance ಆಗಬೇಕು.
18. Distillation ಯಾವಾಗ Use ಮಾಡಬೇಕು?
ಪ್ರತಿಯೊಂದು AI projectಗೂ distillation ಬೇಕು ಎನ್ನುವುದಿಲ್ಲ.
ಇದು particularly useful ಆಗುವುದು:
Smaller Deployment ಬೇಕಾದಾಗ
ಒಂದು large model ಅನ್ನು mobile ಅಥವಾ edge deviceಗೆ deploy ಮಾಡಬೇಕಾದರೆ.
Low Latency ಬೇಕಾದಾಗ
AI response very quickly ಬೇಕಾದ applicationsನಲ್ಲಿ.
Inference Cost ಕಡಿಮೆ ಮಾಡಬೇಕಾದಾಗ
Large-scale AI applicationನಲ್ಲಿ repeated inference expensive ಆಗಿದ್ದರೆ.
Specific Task ಇದ್ದಾಗ
ಒಂದು broad Teacher Modelನ capabilitiesನಲ್ಲಿ specific portion ಮಾತ್ರ ಬೇಕಾದಾಗ.
19. Distillation ಯಾವಾಗ ಸರಿಯಾದ Choice ಆಗಿರದೇ ಇರಬಹುದು?
ಒಂದು modelಗೆ broad capabilities ಮತ್ತು maximum performance ಮುಖ್ಯವಾಗಿದ್ದರೆ, overly aggressive distillation undesirable ಆಗಬಹುದು.
ಉದಾಹರಣೆಗೆ complex reasoning, broad knowledge ಅಥವಾ multiple capabilities ಬೇಕಾಗಿರುವ applicationನಲ್ಲಿ smaller Student Model ಕೆಲವು important capabilities lose ಮಾಡಬಹುದು.
ಅಂತಹ ಸಂದರ್ಭಗಳಲ್ಲಿ:
Large Model
ಅಥವಾ
Hybrid Architecture
better fit ಆಗಬಹುದು.
ಒಂದು practical architecture:
Small Model → Simple Tasks
Large Model → Complex Tasks
ಎಂಬ ರೀತಿಯ routing approach ಆಗಿರಬಹುದು.
20. Futureನಲ್ಲಿ Small AI Models ಯಾಕೆ Important ಆಗಬಹುದು?
AI industryನಲ್ಲಿ ಒಂದು ಕಡೆ increasingly large foundation models develop ಆಗುತ್ತಿವೆ.
ಮತ್ತೊಂದು ಕಡೆ small, efficient ಮತ್ತು specialized models ಕೂಡ ಹೆಚ್ಚು important ಆಗುತ್ತಿವೆ.
ಇದಕ್ಕೆ ಕಾರಣ AI ಎಲ್ಲೆಡೆ deploy ಆಗಬೇಕಾಗಿರುವುದು.
Cloud data centerನಲ್ಲಿ ಮಾತ್ರವಲ್ಲದೆ:
- smartphones
- laptops
- cars
- robots
- cameras
- industrial machines
- IoT devices
ಮುಂತಾದ devicesಲ್ಲೂ AI ಬೇಕಾಗಬಹುದು.
ಈ devicesಗೆ unlimited computing power ಇರುವುದಿಲ್ಲ.
ಆದ್ದರಿಂದ:
AI Future = Large Models + Small Models + Specialized Models
ಎಂಬ combination ಕಾಣಬಹುದು.
AI Agents Future 2026: Smart Assistants Business and Work Future Change Explained
→ Survey on Knowledge Distillation for Large Language Models
21. AI Model Distillation Futureನಲ್ಲಿ ಹೇಗೆ Evolve ಆಗಬಹುದು?
ಮುಂದಿನ AI systems ಇನ್ನಷ್ಟು multimodal ಆಗಬಹುದು.
Text ಮಾತ್ರವಲ್ಲದೆ:
Text + Image + Audio + Video + Sensor Data
ಒಟ್ಟಿಗೆ process ಮಾಡುವ models ಹೆಚ್ಚಾಗಬಹುದು.
ಇಂತಹ models ದೊಡ್ಡದಾದಂತೆ efficiency ಇನ್ನಷ್ಟು important ಆಗುತ್ತದೆ.
ಆಗ distillation techniques ಕೂಡ ಹೆಚ್ಚು sophisticated ಆಗಬಹುದು.
Futureನಲ್ಲಿ:
Teacher Model
↓
Multiple Data Types
↓
Knowledge Transfer
↓
Specialized Student Model
↓
Device / Edge / Cloud Deployment
ಎಂಬ architectureಗಳನ್ನು ನೋಡಬಹುದು.
ಒಂದು ದೊಡ್ಡ general modelನಿಂದ different use casesಗಾಗಿ different small models ರೂಪಿಸುವ ಸಾಧ್ಯತೆಯೂ ಇದೆ.
ಉದಾಹರಣೆಗೆ:
General Teacher
↓
Healthcare Student
Finance Student
Education Student
Mobile Student
Edge Student
ಇವು domain-specific models ಆಗಿರಬಹುದು.
ಆದರೆ ಪ್ರತಿಯೊಂದು domainನಲ್ಲಿ quality, safety ಮತ್ತು evaluation independently verify ಮಾಡಬೇಕಾಗುತ್ತದೆ.
22. AI Model Distillationನ ಒಂದು Simple Real-World Example
ಒಂದು smartphoneನಲ್ಲಿ image recognition feature ಇದೆ ಎಂದುಕೊಳ್ಳಿ.
Original Teacher Model ತುಂಬಾ ದೊಡ್ಡದು.
Phoneನಲ್ಲಿ ಅದನ್ನು run ಮಾಡಲು:
- ಹೆಚ್ಚು memory
- ಹೆಚ್ಚು compute
- ಹೆಚ್ಚು battery
ಬೇಕಾಗಬಹುದು.
ಆದ್ದರಿಂದ developer:
Large Teacher Model
ಬಳಸಿ
Smaller Student Model
train ಮಾಡುತ್ತಾನೆ.
Student Model:
- image patterns ಕಲಿಯುತ್ತದೆ
- Teacher outputsನಿಂದ learning ಪಡೆಯುತ್ತದೆ
- smaller architectureನಲ್ಲಿ deploy ಆಗುತ್ತದೆ
ನಂತರ phoneನಲ್ಲಿ:
Camera → Student Model → Prediction
ಎಂಬ workflow ನಡೆಯಬಹುದು.
Userಗೆ output fast ಆಗಿ ಸಿಗಬಹುದು.
ಇದು AI Model Distillationನ basic idea ಅನ್ನು real-world application ಜೊತೆ connect ಮಾಡುವ simple example.
23. AI Model Distillationನ Biggest Lesson
ಈ entire concept ಅನ್ನು ಒಂದು sentenceನಲ್ಲಿ ಹೇಳಬೇಕಾದರೆ:
“ಒಂದು ದೊಡ್ಡ AI modelನ useful intelligence ಅನ್ನು smaller modelನಲ್ಲಿ ಹೆಚ್ಚು efficiently ಪಡೆಯಲು ಪ್ರಯತ್ನಿಸುವುದು AI Model Distillation.”
ಇದು model ಅನ್ನು simply shrink ಮಾಡುವುದು ಅಲ್ಲ.
ಇದು:
Teacher Knowledge
Student Training
Distillation Objective
Performance Evaluation
ಎಂಬ combined process.
ಅಂತಿಮ goal:
Smaller Model + Useful Capability + Better Efficiency
ಇವುಗಳ ನಡುವೆ practical balance ಹುಡುಕುವುದು.
Key Takeaways
- AI Model Distillation Teacher Modelನ useful knowledge ಅನ್ನು Student Modelಗೆ transfer ಮಾಡುವ technique.
- Teacher Model ಸಾಮಾನ್ಯವಾಗಿ ದೊಡ್ಡ ಮತ್ತು ಹೆಚ್ಚು capable ಆಗಿರುತ್ತದೆ.
- Student Model smaller ಮತ್ತು resource-efficient ಆಗಿರಬಹುದು.
- Soft Targets Studentಗೆ hard labelsಗಿಂತ richer learning signal ನೀಡಬಹುದು.
- Temperature soft probability distribution ಅನ್ನು control ಮಾಡಲು ಬಳಸಬಹುದು.
- Distillation model size ಮತ್ತು inference cost ಕಡಿಮೆ ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
- Mobile AI ಮತ್ತು Edge AIನಲ್ಲಿ smaller models useful ಆಗಬಹುದು.
- Enterprise applicationsನಲ್ಲಿ specific tasksಗಾಗಿ distilled models ಬಳಸುವ ಸಾಧ್ಯತೆ ಇದೆ.
- Distillationನಲ್ಲಿ accuracy ಮತ್ತು efficiency ನಡುವೆ trade-off ಇರಬಹುದು.
- Student Model Teacherನ ಎಲ್ಲಾ capabilities ಅನ್ನು perfectly retain ಮಾಡುತ್ತದೆ ಎಂದು guarantee ಇಲ್ಲ.
- Teacher Modelನ quality ಮತ್ತು training data ಕೂಡ result ಮೇಲೆ ಪರಿಣಾಮ ಬೀರುತ್ತವೆ.
- Future AI ecosystemನಲ್ಲಿ Large Models + Small Models + Specialized Models ಒಟ್ಟಿಗೆ coexist ಮಾಡುವ ಸಾಧ್ಯತೆ ಇದೆ.
In This Article You Learned
ಈ articleನಲ್ಲಿ AI Model Distillation ಎಂದರೇನು ಮತ್ತು ಅದು ಯಾಕೆ important ಎಂಬುದನ್ನು beginner-friendly Kannada + English hybrid languageನಲ್ಲಿ ನೋಡಿದ್ದೇವೆ.
ಮೊದಲು Teacher Model ಮತ್ತು Student Model concept ಅರ್ಥಮಾಡಿಕೊಂಡೆವು.
ನಂತರ Teacher Modelನ predictions ಮತ್ತು Soft Targets ಬಳಸಿಕೊಂಡು Student Model ಹೇಗೆ learning ಪಡೆಯುತ್ತದೆ ಎಂಬುದನ್ನು step-by-step ನೋಡಿದೆವು.
Hard Labels, Soft Labels, Temperature ಮತ್ತು Distillation Loss concepts ಕೂಡ ಅರ್ಥಮಾಡಿಕೊಂಡೆವು.
ಮುಂದೆ model distillationನ advantages ಮತ್ತು limitations ನೋಡಿದೆವು.
ಅದರ ನಂತರ:
- Mobile AI
- Edge AI
- Enterprise AI
- On-device AI
- Specialized AI Models
ಮುಂತಾದ real-world applicationsನಲ್ಲಿ distillation ಹೇಗೆ useful ಆಗಬಹುದು ಎಂಬುದನ್ನು ನೋಡಿದೆವು.
ಕೊನೆಯಲ್ಲಿ future AI landscapeನಲ್ಲಿ large models ಜೊತೆಗೆ smaller ಮತ್ತು specialized models ಯಾಕೆ important ಆಗಬಹುದು ಎಂಬುದನ್ನು ನೋಡಿದೆವು.
ಮುಖ್ಯವಾಗಿ ನೆನಪಿಟ್ಟುಕೊಳ್ಳಬೇಕಾದ concept:
Teacher Modelನ full size ಅನ್ನು carry ಮಾಡದೇ, ಅದರ useful knowledgeನಿಂದ smaller Student Model ಅನ್ನು ಹೆಚ್ಚು efficient ಆಗಿ train ಮಾಡುವುದು AI Model Distillationನ core idea.
Final Article Summary
AI models ದಿನದಿಂದ ದಿನಕ್ಕೆ ಹೆಚ್ಚು powerful ಆಗುತ್ತಿವೆ. ಆದರೆ model size ಮತ್ತು capability ಹೆಚ್ಚಾದಂತೆ compute, memory, energy ಮತ್ತು inference cost ಕೂಡ important concerns ಆಗುತ್ತವೆ.
ಇಂತಹ situationನಲ್ಲಿ AI Model Distillation ಒಂದು useful optimization technique ಆಗಬಹುದು.
ಇದರಲ್ಲಿ ದೊಡ್ಡ Teacher Modelನ outputs ಮತ್ತು learned behaviour ಅನ್ನು ಬಳಸಿಕೊಂಡು smaller Student Modelಗೆ training ನೀಡಲಾಗುತ್ತದೆ.
Student Model Teacher Modelಗಿಂತ smaller ಆಗಿದ್ದರೂ, ಅದರ useful capabilitiesನ ಒಂದು ಭಾಗವನ್ನು retain ಮಾಡಲು ಪ್ರಯತ್ನಿಸುತ್ತದೆ.
ಇದರ ಮೂಲಕ ಕೆಲವು applicationsನಲ್ಲಿ:
Smaller Size → Faster Inference → Lower Resource Usage → Easier Deployment
ಎಂಬ benefits ಸಿಗಬಹುದು.
ಆದರೆ distillationಗೆ limitations ಕೂಡ ಇವೆ.
Student Modelನಲ್ಲಿ ಕೆಲವು knowledge ಅಥವಾ accuracy loss ಆಗಬಹುದು. Teacher Modelನ quality, training strategy ಮತ್ತು evaluation ಕೂಡ final resultನಲ್ಲಿ important.
ಆದ್ದರಿಂದ ಉತ್ತಮ distilled model ಎಂದರೆ ಅತ್ಯಂತ ಚಿಕ್ಕ model ಅಲ್ಲ.
ಬದಲಾಗಿ:
ಅಗತ್ಯವಿರುವ performance ಅನ್ನು retain ಮಾಡಿಕೊಂಡು, ಸಾಧ್ಯವಾದಷ್ಟು efficient ಆಗಿರುವ model.
Futureನಲ್ಲಿ AI cloud serversನಲ್ಲಿ ಮಾತ್ರವಲ್ಲದೆ smartphones, vehicles, robots, cameras ಮತ್ತು IoT devicesಗಳಲ್ಲೂ ಹೆಚ್ಚಾಗಿ ಕಾಣಿಸಿಕೊಳ್ಳುವ ಸಾಧ್ಯತೆಯಿದೆ.
ಅದಕ್ಕಾಗಿ small and efficient AI modelsನ importance ಕೂಡ ಹೆಚ್ಚಾಗಬಹುದು.
Conclusion
AI industryನಲ್ಲಿ ಒಂದು interesting direction ನಡೆಯುತ್ತಿದೆ.
ಒಂದು ಕಡೆ increasingly powerful Large AI Models ನಿರ್ಮಾಣವಾಗುತ್ತಿವೆ.
ಮತ್ತೊಂದು ಕಡೆ ಅವುಗಳ capabilities ಅನ್ನು practical devices ಮತ್ತು applicationsಗೆ ತರುವ ಅಗತ್ಯ ಹೆಚ್ಚಾಗುತ್ತಿದೆ.
ಇಲ್ಲಿಯೇ AI Model Distillation ಒಂದು bridge ಆಗಿ ಕೆಲಸ ಮಾಡಬಹುದು.
Large Teacher Model
↓
Knowledge Transfer
↓
Smaller Student Model
↓
Efficient Deployment
ಈ basic workflow ಮೂಲಕ ದೊಡ್ಡ AI modelನ useful behaviour ಅನ್ನು smaller modelನಲ್ಲಿ ಪಡೆಯಲು ಪ್ರಯತ್ನಿಸಲಾಗುತ್ತದೆ.
ಇದರ biggest advantage efficiency.
ಒಂದು large modelಗೆ ಬೇಕಾಗುವ computing resources ಎಲ್ಲ ಸಂದರ್ಭದಲ್ಲೂ available ಇರಬೇಕೆಂದಿಲ್ಲ.
ಆದರೆ ಒಂದು smaller model specific task ಅನ್ನು sufficiently well perform ಮಾಡಿದರೆ, ಅದು mobile, edge ಮತ್ತು enterprise environmentsನಲ್ಲಿ ಹೆಚ್ಚು practical ಆಗಬಹುದು.
ಆದರೆ distillationನಲ್ಲಿ ಒಂದು important balance ಇದೆ:
Smaller ≠ Automatically Better
Faster ≠ Automatically More Accurate
Cheaper ≠ Automatically More Capable
ಅದರ ಬದಲು goal:
Right Size + Right Capability + Right Efficiency
ಎಂಬ balance.
ಮುಂದಿನ ವರ್ಷಗಳಲ್ಲಿ AI models ಇನ್ನಷ್ಟು powerful ಆಗುತ್ತಾ ಹೋದಂತೆ, ಅವುಗಳನ್ನು efficiently deploy ಮಾಡುವ technologyಗಳ importance ಕೂಡ ಹೆಚ್ಚಾಗಬಹುದು.
ಆದ್ದರಿಂದ AI Model Distillation ಒಂದು technical Machine Learning concept ಮಾತ್ರವಲ್ಲ.
ಇದು “Big AI ಅನ್ನು practical AI ಆಗಿ ಹೇಗೆ ಮಾಡುವುದು?” ಎಂಬ ದೊಡ್ಡ ಪ್ರಶ್ನೆಗೆ ಒಂದು important answer ಆಗಿದೆ.
Frequently Asked Questions
1. AI Model Distillation ಎಂದರೇನು?
AI Model Distillation ಎಂದರೆ ದೊಡ್ಡ Teacher Modelನ useful knowledge ಮತ್ತು behaviour ಅನ್ನು smaller Student Modelಗೆ transfer ಮಾಡಿ train ಮಾಡುವ Machine Learning technique.
2. Teacher Model ಎಂದರೇನು?
Teacher Model ಎಂದರೆ ಸಾಮಾನ್ಯವಾಗಿ ಹೆಚ್ಚು capable ಮತ್ತು ದೊಡ್ಡ pretrained AI model. ಇದು Student Modelಗೆ learning signal ನೀಡುತ್ತದೆ.
3. Student Model ಎಂದರೇನು?
Student Model Teacherಗಿಂತ smaller model ಆಗಿದ್ದು, ಅದರ useful capabilities ಅನ್ನು ಕಡಿಮೆ resourcesನಲ್ಲಿ reproduce ಮಾಡಲು train ಮಾಡಲಾಗುತ್ತದೆ.
4. Knowledge Distillation ಮತ್ತು AI Model Distillation ಒಂದೇನಾ?
ಈ contextನಲ್ಲಿ AI Model Distillation ಎನ್ನುವುದು ಸಾಮಾನ್ಯವಾಗಿ Knowledge Distillation conceptನ್ನೇ ಸೂಚಿಸುತ್ತದೆ — Teacher Modelನ outputs ಅಥವಾ knowledge ಬಳಸಿ Student Model train ಮಾಡುವುದು.
5. Soft Targets ಎಂದರೇನು?
Teacher Modelನ probability-based outputs ಅಥವಾ richer predictions ಅನ್ನು Soft Targets ಎಂದು ಕರೆಯಲಾಗುತ್ತದೆ. ಇವು Studentಗೆ final correct labelಗಿಂತ ಹೆಚ್ಚು learning information ನೀಡಬಹುದು.
6. Temperature ಯಾಕೆ ಬಳಸುತ್ತಾರೆ?
Distillation trainingನಲ್ಲಿ Teacherನ probability distribution ಅನ್ನು softer ಆಗಿ ಮಾಡಿಸಿ class relationships ಬಗ್ಗೆ ಹೆಚ್ಚು useful learning signal ನೀಡಲು temperature parameter ಬಳಸಬಹುದು.
7. AI Model Distillation model ಅನ್ನು faster ಮಾಡುತ್ತದೆಯೇ?
Smaller Student Model ಕಡಿಮೆ computation ಬೇಕಾಗುವಂತೆ designed ಆಗಿದ್ದರೆ inference faster ಆಗುವ ಸಾಧ್ಯತೆ ಇದೆ. ಆದರೆ actual speed improvement hardware ಮತ್ತು architecture ಮೇಲೆ depend ಆಗುತ್ತದೆ.
8. Distillation accuracy ಕಡಿಮೆ ಮಾಡಬಹುದೇ?
ಹೌದು, ಕೆಲವು situationsನಲ್ಲಿ Student Model Teacher Modelಗಿಂತ ಕಡಿಮೆ accuracy ಅಥವಾ capabilities ಹೊಂದಿರಬಹುದು. ಆದ್ದರಿಂದ performance evaluation ಮುಖ್ಯ.
9. AI Model Distillation Mobile AIಗೆ usefulನಾ?
ಹೌದು. Smaller models mobile ಮತ್ತು edge devicesನಲ್ಲಿ deploy ಮಾಡಲು ಹೆಚ್ಚು practical ಆಗಬಹುದು, ವಿಶೇಷವಾಗಿ compute ಮತ್ತು memory constraints ಇರುವ ಸಂದರ್ಭಗಳಲ್ಲಿ.
10. AI Model Distillation ಮತ್ತು Model Compression ನಡುವಿನ ವ್ಯತ್ಯಾಸ ಏನು?
Model Compression model size ಅಥವಾ resource requirements ಕಡಿಮೆ ಮಾಡುವ broad category. Knowledge Distillation Teacher Modelನ knowledge ಬಳಸಿ Student Model train ಮಾಡುವ specific technique.
11. Distilled Model Teacher Modelನಂತೆ powerful ಆಗಿರುತ್ತದೆಯೇ?
ಅಗತ್ಯವಿಲ್ಲ. Student Modelನ goal ಸಾಮಾನ್ಯವಾಗಿ Teacherನ useful capabilitiesನ ಒಂದು ಭಾಗವನ್ನು smaller ಮತ್ತು more efficient architectureನಲ್ಲಿ retain ಮಾಡುವುದು.
12. Futureನಲ್ಲಿ AI Model Distillation ಯಾಕೆ important ಆಗಬಹುದು?
AI smartphones, edge devices, robots, vehicles ಮತ್ತು IoT systemsಗೆ expand ಆಗುತ್ತಿದ್ದಂತೆ smaller, faster ಮತ್ತು resource-efficient modelsನ demand ಹೆಚ್ಚಾಗಬಹುದು.
Continue Learning
AI Model Distillation ಅರ್ಥವಾದ ನಂತರ AI models ಹೇಗೆ build ಮತ್ತು operate ಆಗುತ್ತವೆ ಎಂಬುದನ್ನು ಇನ್ನಷ್ಟು ತಿಳಿಯಲು:
→ AI Model vs AI Tool Explained: 7 Powerful Differences Every Beginner Must Know for Better Learning in 2026
→ Reasoning AI Models Explained: How They Think Before They Answer
→ Multimodal AI ಅಂದ್ರೆ ಏನು? Text + Image + Audio AI Systems ಹೇಗೆ ಕೆಲಸ ಮಾಡುತ್ತವೆ? (2026 Guide)
→ The Ultimate Guide to How AI Agents Work: Memory, Planning, Tools and Real-World Examples
Final CTA
AI model ದೊಡ್ಡದಾಗಿರುವುದು ಮಾತ್ರ ಅದರ usefulness ಅನ್ನು ನಿರ್ಧರಿಸುವುದಿಲ್ಲ.
ಎಲ್ಲಿ deploy ಮಾಡಬೇಕು, ಎಷ್ಟು compute ಬೇಕು, ಎಷ್ಟು fast ಆಗಿ response ಕೊಡಬೇಕು ಮತ್ತು ಎಷ್ಟು performance retain ಮಾಡಬೇಕು ಎಂಬುದೂ equally important.
AI Model Distillation ಈ challengeಗೆ interesting solution ನೀಡುತ್ತದೆ:
Big AIನ useful knowledge → Small AIನ efficient deployment
AI Models, AI Optimization, Small AI, Edge AI ಮತ್ತು future Artificial Intelligence technologies ಬಗ್ಗೆ ಇನ್ನಷ್ಟು Kannada + English hybrid articlesಗಾಗಿ AI Kannada Techನಲ್ಲಿ ಮುಂದುವರಿದು ಓದಿ.