Vision Language Models Explained: How AI Connects Images, Text and Real-World Understanding
Introduction
Vision Language Models (VLMs) Artificial Intelligenceನಲ್ಲಿ ಒಂದು important evolution ಆಗಿವೆ. Earlier AIಗೆ text understand ಮಾಡುವುದು ಒಂದು capability ಆಗಿತ್ತು, image understand ಮಾಡುವುದು ಮತ್ತೊಂದು separate capability ಆಗಿತ್ತು.
ಆದರೆ ಈಗ Vision Language Models visual information ಮತ್ತು language information ಎರಡನ್ನೂ ಒಂದೇ AI systemನಲ್ಲಿ process ಮಾಡಬಹುದು.
Imagine ಮಾಡಿ:
ನೀವು ಒಂದು photo upload ಮಾಡಿ ಕೇಳುತ್ತೀರಿ:
“ಈ pictureನಲ್ಲಿ ಏನು ನಡೆಯುತ್ತಿದೆ?”
AI
↓
Image Understanding
Language Understanding
↓
Context Analysis
↓
Reasoning
↓
Natural Language Answer
ಇದೇ Vision Language Modelsನ basic power.
ಇದರಿಂದ AI ಕೇವಲ words read ಮಾಡುವ system ಆಗಿರದೆ, ನೋಡಿದ information ಅನ್ನು language ಮೂಲಕ explain ಮಾಡುವ intelligent system ಆಗಿ evolve ಆಗುತ್ತಿದೆ.
What Are Vision Language Models?
ಸರಳವಾಗಿ ಹೇಳುವುದಾದರೆ, Vision Language Models ಎಂದರೆ images ಅಥವಾ visual information ಮತ್ತು natural language ಎರಡನ್ನೂ understand ಮಾಡಿ ಅವುಗಳ ನಡುವೆ connection ನಿರ್ಮಿಸುವ AI models.
ಒಂದು VLMಗೆ ನೀವು
📷 Image
💬 Question
ಕೊಟ್ಟರೆ,
ಅದು imageನಲ್ಲಿ ಇರುವ objects, text, relationships ಮತ್ತು visual context analyse ಮಾಡಿ languageನಲ್ಲಿ answer generate ಮಾಡಬಹುದು.
Example:
Input
ಒಂದು restaurant menu photo
“Vegetarian dishes ಯಾವುವು?”
↓
Vision Language Model
↓
Text Detection
↓
Food Recognition
↓
Menu Understanding
↓
Answer
ಇಲ್ಲಿ AI imageನಲ್ಲಿರುವ information ಅನ್ನು language query ಜೊತೆ connect ಮಾಡುತ್ತದೆ.
Google Cloud’s overview of multimodal AI explains how models can combine text, images, video and other information types.
Multimodal AI Systems Break New Ground with Smarter Human–AI Interaction
Why Vision Language Models Matter
Traditional AI systemsನಲ್ಲಿ different tasksಗೆ different models ಬೇಕಾಗುತ್ತಿತ್ತು.
Earlier:
Image
↓
Computer Vision Model
Text
↓
Language Model
Voice
↓
Speech Model
ಆದರೆ modern AI architectureನಲ್ಲಿ multiple capabilities ಒಂದೇ ecosystemನಲ್ಲಿ combine ಆಗುತ್ತಿವೆ.
Image
Text
↓
Vision Language Model
↓
Understanding
↓
Reasoning
↓
Response
ಇದರಿಂದ users AI ಜೊತೆ ಹೆಚ್ಚು natural ರೀತಿಯಲ್ಲಿ interact ಮಾಡಬಹುದು.
How Vision Language Models Work
Basic workflow ಹೀಗಿರುತ್ತದೆ:
User Input
↓
Image / Visual Information
Text Prompt
↓
Vision Encoder
↓
Visual Features
↓
Language Model
↓
Multimodal Reasoning
↓
Text Response
ಉದಾಹರಣೆಗೆ ನೀವು ಒಂದು damaged machine photo upload ಮಾಡಿ,
“ಈ machineನಲ್ಲಿ visible problem ಏನು?” ಎಂದು ಕೇಳಿದರೆ,
model ಮೊದಲು visual features identify ಮಾಡುತ್ತದೆ.
ನಂತರ questionನ meaning understand ಮಾಡಿ,
ಎರಡನ್ನೂ combine ಮಾಡಿ response generate ಮಾಡುತ್ತದೆ.
For a deeper technical introduction, see this Vision Language Models guide from Hugging Face.
Open-Weight AI Models Explained
Vision Encoder ಅಂದ್ರೆ ಏನು?
Vision Encoder VLM architectureನ ಪ್ರಮುಖ component.
ಇದು image ಅನ್ನು directly human ರೀತಿಯಲ್ಲಿ “ನೋಡುವುದಿಲ್ಲ”.
ಬದಲಾಗಿ imageನ visual information ಅನ್ನು AI process ಮಾಡಬಹುದಾದ numerical representations ಅಥವಾ features ಆಗಿ convert ಮಾಡುತ್ತದೆ.
Image
↓
Vision Encoder
↓
Visual Features
↓
Language Model
↓
Meaning
↓
Answer
ಉದಾಹರಣೆಗೆ ಒಂದು car photoನಲ್ಲಿ
- Car
- Road
- Traffic Signal
- People
- Buildings
ಇತ್ಯಾದಿ visual information identify ಆಗಬಹುದು.
Language Modelನ Role
Visual information ಮಾತ್ರ ಸಾಕಾಗುವುದಿಲ್ಲ.
User question ಕೂಡ understand ಆಗಬೇಕು.
ಅಲ್ಲಿಗೆ Language Model ಬರುತ್ತದೆ.
Image
Question
↓
Vision Encoder
Language Understanding
↓
Context
↓
Reasoning
↓
Answer
ಉದಾಹರಣೆಗೆ:
“ಈ imageನಲ್ಲಿ ಎಷ್ಟು people ಇದ್ದಾರೆ?”
ಮತ್ತು
“ಈ imageನಲ್ಲಿ ಏನು ನಡೆಯುತ್ತಿದೆ?”
ಎರಡೂ questions same image ಬಗ್ಗೆ ಇದ್ದರೂ, model different types of answers generate ಮಾಡಬೇಕು.
Language understanding ಇದನ್ನು possible ಮಾಡುತ್ತದೆ.
Vision + Language = Better Context
ಒಂದು imageನಲ್ಲಿ ಹಲವು objects ಇರಬಹುದು.
ಆದರೆ user ಯಾವ object ಬಗ್ಗೆ ಕೇಳುತ್ತಿದ್ದಾರೆ ಎನ್ನುವುದನ್ನು language prompt specify ಮಾಡುತ್ತದೆ.
Example:
📷 Classroom Image
Question:
“Teacher ಯಾವ sideನಲ್ಲಿ ನಿಂತಿದ್ದಾರೆ?”
↓
Visual Understanding
Question Understanding
↓
Spatial Relationship
↓
Answer
ಇದರಿಂದ AIಗೆ visual context + language context ಎರಡೂ ಸಿಗುತ್ತವೆ.
Real-World Example: Document Understanding
ಒಂದು invoice photo upload ಮಾಡಿ:
“Total amount ಎಷ್ಟು?”
VLM workflow:
Invoice Image
↓
Visual Analysis
↓
OCR / Text Recognition
↓
Field Identification
↓
Total Amount Detection
↓
Answer
ಇದರಿಂದ users manually document type ಮಾಡಬೇಕಾದ ಕೆಲಸ ಕಡಿಮೆಯಾಗುತ್ತದೆ.
Vision Language Models in Healthcare
Healthcareನಲ್ಲಿ visual information ತುಂಬಾ important.
Medical Image
Patient Information
Doctor Question
↓
AI Analysis
↓
Visual Pattern Detection
↓
Context Understanding
↓
Clinical Support
↓
Doctor Review
ಇಂತಹ systems medical professionalsಗೆ decision-support tool ಆಗಿ ಉಪಯೋಗವಾಗಬಹುದು.
AI doctorನ professional judgement replace ಮಾಡುವುದಲ್ಲ; supporting information provide ಮಾಡುವುದು ಮುಖ್ಯ.
Vision Language Models in Education
Educationನಲ್ಲಿ VLMs interactive learningಗೆ ಹೊಸ possibilities create ಮಾಡುತ್ತಿವೆ.
Student
↓
Textbook Photo
Question
↓
Vision Language Model
↓
Page Understanding
↓
Concept Identification
↓
Simple Explanation
↓
Practice Question
ಒಬ್ಬ student Kannadaನಲ್ಲಿ ಕೇಳಿದರೂ, system supported languagesನಲ್ಲಿ explanation ನೀಡಬಹುದು.
Vision Language Models in Retail
Retailನಲ್ಲಿ customer product photo upload ಮಾಡಿ ಪ್ರಶ್ನೆ ಕೇಳಬಹುದು.
Product Image
↓
VLM
↓
Product Identification
↓
Visual Features
↓
Customer Question
↓
Recommendation
Example:
“ಈ shirtಗೆ similar design ಇದೆಯಾ?”
AI image characteristics analyse ಮಾಡಿ relevant products ಹುಡುಕಲು ಸಹಾಯ ಮಾಡಬಹುದು.
Vision Language Models in Manufacturing
Factoriesನಲ್ಲಿ cameras already large-scale use ಆಗುತ್ತಿವೆ.
Future workflow:
Factory Camera
↓
Product Image
↓
Vision Language Model
↓
Defect Detection
↓
Visual Explanation
↓
Quality Team
↓
Decision
ಇದರಿಂದ simple defect detection ಜೊತೆಗೆ visual reasoning and explanation ಕೂಡ possible ಆಗಬಹುದು.
Vision Language Models in Accessibility
ಈ technology visually impaired usersಗೆ ಕೂಡ useful ಆಗಬಹುದು.
Camera
↓
VLM
↓
Object Recognition
↓
Scene Understanding
↓
Voice Description
↓
User
ಉದಾಹರಣೆಗೆ AI:
“ನಿಮ್ಮ ಮುಂದೆ ಒಂದು table ಇದೆ. ಅದರ ಮೇಲೆ laptop ಮತ್ತು ಒಂದು water bottle ಇದೆ.”
ಎಂದು describe ಮಾಡಬಹುದು.
ಇದರಿಂದ visual information ಅನ್ನು audio ಮೂಲಕ accessible ಮಾಡಬಹುದು.
Vision Language Models vs Traditional Computer Vision
Traditional Computer Vision
Image
↓
Object Detection
↓
Label
Vision Language Model
Image
Natural Language Question
↓
Visual Understanding
↓
Context
↓
Reasoning
↓
Natural Language Explanation
ಇದು major difference.
Traditional computer vision specific visual taskನಲ್ಲಿ strong ಆಗಿರಬಹುದು.
VLMs visual information ಮತ್ತು language interaction combine ಮಾಡುತ್ತವೆ.
Major Benefits
Vision Language Models ಹಲವಾರು advantages ಕೊಡುತ್ತವೆ:
✔ Image + Text Understanding
✔ Natural Language Interaction
✔ Document Analysis
✔ Visual Question Answering
✔ Better Context Understanding
✔ Accessibility
✔ Intelligent Search
✔ Visual Assistance
✔ Business Automation
✔ Human–AI Collaboration
Current Challenges
Technology powerful ಆದರೂ ಕೆಲವು limitations ಇವೆ.
Hallucinations
ಕೆಲವೊಮ್ಮೆ model imageನಲ್ಲಿ ಇಲ್ಲದ information ಅನ್ನು incorrectly ಹೇಳಬಹುದು.
Small Details
Tiny text ಅಥವಾ low-resolution images correctly understand ಮಾಡುವುದು difficult ಆಗಬಹುದು.
Complex Reasoning
ಒಂದು imageನಿಂದ deep real-world conclusion ತೆಗೆದುಕೊಳ್ಳುವುದು ಇನ್ನೂ challenging.
Bias
Training dataನಲ್ಲಿ bias ಇದ್ದರೆ model output ಮೇಲೂ ಪರಿಣಾಮ ಬೀಳಬಹುದು.
Privacy
Personal photos, documents ಹಾಗೂ surveillance images sensitive data ಆಗಿರಬಹುದು.
AI Voice Cloning Ethics and Safety
Why Vision Language Models Are Important for the Future
AI futureನಲ್ಲಿ humans computerಗೆ information ನೀಡುವ ವಿಧಾನವೇ change ಆಗಬಹುದು.
Earlier
Keyboard
↓
Text
↓
AI
Future
Voice
Image
Video
Text
↓
Vision Language Models
↓
Understanding
↓
Reasoning
↓
Action
ಅಂದರೆ AI ಜೊತೆ communication increasingly multimodal ಮತ್ತು natural ಆಗುತ್ತದೆ.
How AI Learns to Understand Images + Text Together
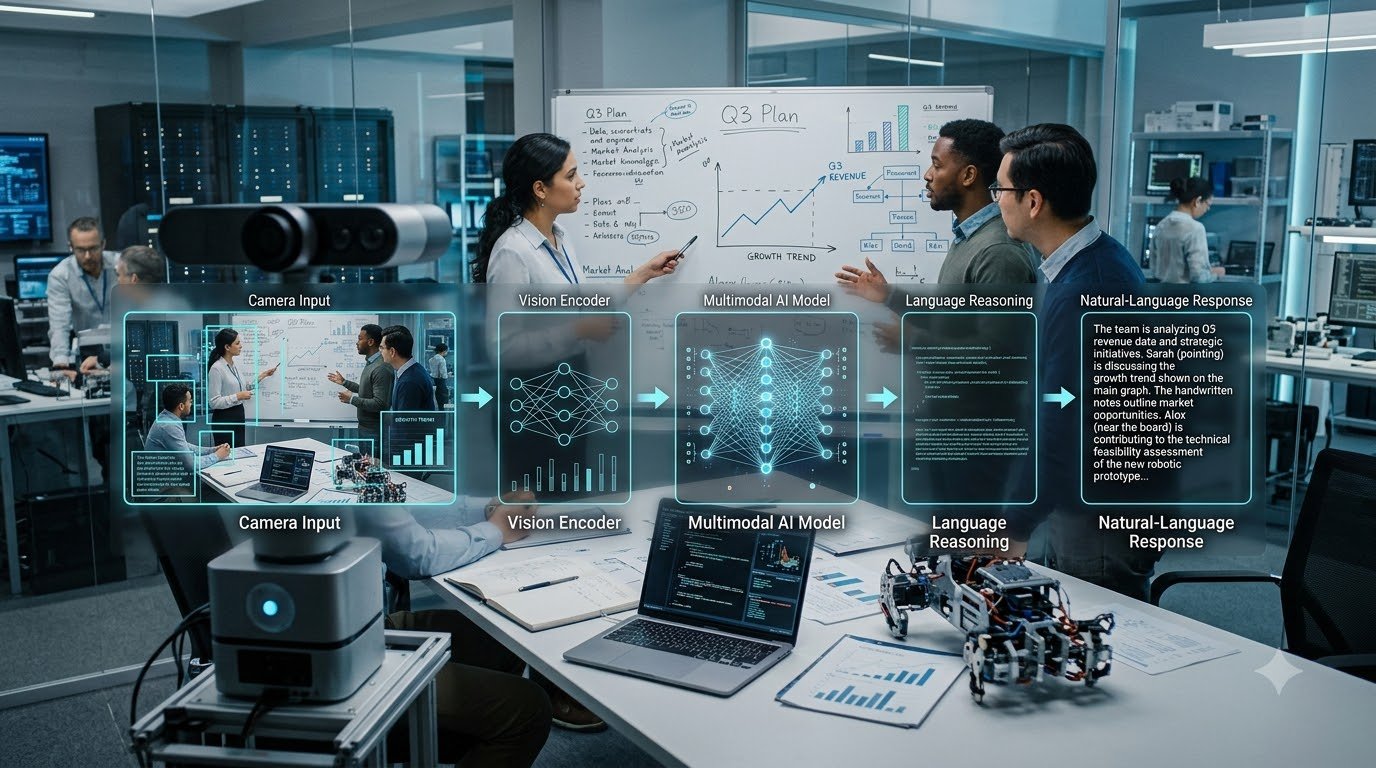
ಇಲ್ಲಿಯವರೆಗೆ ನಾವು Vision Language Models (VLMs) ಅಂದರೆ ಏನು, ಅವು ಯಾಕೆ important ಅನ್ನೋದನ್ನು ನೋಡಿದ್ದೇವೆ. ಈಗ main question: ಒಂದು AI model image ಅನ್ನು “ನೋಡಿ”, ಅದರಲ್ಲಿರುವ meaning ಅನ್ನು ಅರ್ಥಮಾಡಿಕೊಂಡು, ಅದಕ್ಕೆ ಸಂಬಂಧಿಸಿದ natural-language answer ಹೇಗೆ ಕೊಡುತ್ತದೆ?
ಇದು simple image recognitionಗಿಂತ ತುಂಬಾ advanced concept. Traditional computer vision system ಒಂದು imageನಲ್ಲಿ “ಇದು car”, “ಇದು person”, “ಇದು document” ಎಂದು identify ಮಾಡಬಹುದು. ಆದರೆ VLM ಒಂದು ಹೆಜ್ಜೆ ಮುಂದೆ ಹೋಗಿ image + text + context + reasoning ಅನ್ನು ಒಟ್ಟಿಗೆ process ಮಾಡಲು ಪ್ರಯತ್ನಿಸುತ್ತದೆ.
Quick Summary
Vision Language Models ಎಂದರೆ visual information ಮತ್ತು language information ಎರಡನ್ನೂ ಒಟ್ಟಿಗೆ ಅರ್ಥಮಾಡಿಕೊಳ್ಳಲು designed ಮಾಡಿರುವ AI models.
ಸರಳವಾಗಿ:
Image → Visual Understanding → Multimodal Fusion → Reasoning → Language Response
ಉದಾಹರಣೆಗೆ, ನೀವು ಒಂದು restaurant bill photo upload ಮಾಡಿ:
“ಈ billನಲ್ಲಿ total amount ಎಷ್ಟು?”
ಎಂದು ಕೇಳಿದರೆ, VLM ಕೇವಲ imageನಲ್ಲಿ numbers detect ಮಾಡುವುದಲ್ಲ. ಅದು document structure ಅನ್ನು ಅರ್ಥಮಾಡಿಕೊಂಡು, relevant amount identify ಮಾಡಿ, ನಂತರ answer ಅನ್ನು text ರೂಪದಲ್ಲಿ ನೀಡುತ್ತದೆ.
ಅದೇ ಕಾರಣಕ್ಕೆ VLMs ಇಂದು document analysis, healthcare imaging, education, manufacturing, robotics, accessibility ಮತ್ತು AI assistants ಮುಂತಾದ ಹಲವು ಕ್ಷೇತ್ರಗಳಲ್ಲಿ useful ಆಗುತ್ತಿವೆ.
Table of Contents
- What Are Vision Language Models?
- Traditional Computer Vision vs VLMs
- How Vision Language Models Work
- Vision Encoder ಎಂದರೇನು?
- Language Model ಹೇಗೆ Connect ಆಗುತ್ತದೆ?
- Multimodal Fusion ಹೇಗೆ ನಡೆಯುತ್ತದೆ?
- VLMs Imageನಲ್ಲಿ ಏನು ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಹುದು?
- Real-World Examples
- Vision Language Models in Education
- VLMs in Business and Documents
- VLMs in Manufacturing and Robotics
- Benefits and Limitations
- Why VLMs Matter for the Future
1. What Are Vision Language Models?
Vision Language Models ಅಥವಾ VLMs ಅಂದರೆ images ಮತ್ತು natural language ಎರಡನ್ನೂ process ಮಾಡುವ multimodal AI systems.
ಸಾಮಾನ್ಯ language model mainly text ಮೇಲೆ ಕೆಲಸ ಮಾಡುತ್ತದೆ. ಅದು words, sentences, documents ಮತ್ತು instructions ಅರ್ಥಮಾಡಿಕೊಳ್ಳುತ್ತದೆ.
Computer vision model ಮತ್ತೊಂದೆಡೆ images ಅಥವಾ video data ಅನ್ನು analyze ಮಾಡುತ್ತದೆ.
ಆದರೆ VLM ಈ ಎರಡು capabilities ಅನ್ನು ಒಂದೇ AI systemನಲ್ಲಿ combine ಮಾಡುತ್ತದೆ.
Simple Example
ಒಂದು imageನಲ್ಲಿ:
- ಒಂದು red car ಇದೆ
- road ಇದೆ
- traffic signal ಇದೆ
- ಇಬ್ಬರು people ಇದ್ದಾರೆ
ನೀವು AIಗೆ:
“ಈ imageನಲ್ಲಿ traffic situation ಹೇಗಿದೆ?”
ಎಂದು ಕೇಳಿದರೆ, VLM visual elements ಅನ್ನು identify ಮಾಡಿ, ಅವುಗಳ relationship ಅನ್ನು ಅರ್ಥಮಾಡಿಕೊಂಡು languageನಲ್ಲಿ answer generate ಮಾಡಬಹುದು.
ಅಂದರೆ:
Seeing + Understanding + Language = Vision Language Model
ಇದು ಕೇವಲ “image recognition” ಅಲ್ಲ. Visual informationಗೆ language meaning connect ಮಾಡುವ capability ಇದಾಗಿದೆ.
2. Traditional Computer Vision vs Vision Language Models
ಹಳೆಯ computer vision systems ಸಾಮಾನ್ಯವಾಗಿ predefined task ಮೇಲೆ ಹೆಚ್ಚು focus ಮಾಡುತ್ತವೆ.
ಉದಾಹರಣೆಗೆ:
Image → Object Detection → “Car”
ಅಥವಾ:
Image → Face Detection → “Face Found”
ಇಲ್ಲಿ modelಗೆ task ಮೊದಲೇ define ಮಾಡಿರಬಹುದು.
VLM approach ಹೆಚ್ಚು flexible ಆಗಿರುತ್ತದೆ.
Image + Question → AI Understanding → Answer
Comparison
| Feature | Traditional Computer Vision | Vision Language Models |
|---|---|---|
| Main Input | Image/Video | Image + Text |
| Output | Labels/Predictions | Natural-language response |
| Context Understanding | Limited/Task-specific | More flexible |
| Question Answering | Usually limited | Stronger capability |
| Document Understanding | Specific systems needed | Can combine vision + language |
| Reasoning | Task-dependent | Multimodal reasoning possible |
| Interaction | Limited | Conversational |
ಇದರಿಂದ VLMs AI assistantsಗೆ visual understanding add ಮಾಡುತ್ತವೆ.
ಉದಾಹರಣೆಗೆ, text-only assistantಗೆ ಒಂದು damaged machine photo ತೋರಿಸಿದರೆ ಅದು imageನ physical condition directly inspect ಮಾಡಲು ಸಾಧ್ಯವಿಲ್ಲ. ಆದರೆ vision capability ಇರುವ multimodal system photoನಲ್ಲಿ ಕಾಣುವ information ಅನ್ನು process ಮಾಡಬಹುದು.
3. How Vision Language Models Work
ಇದು VLM architectureನ most important part.
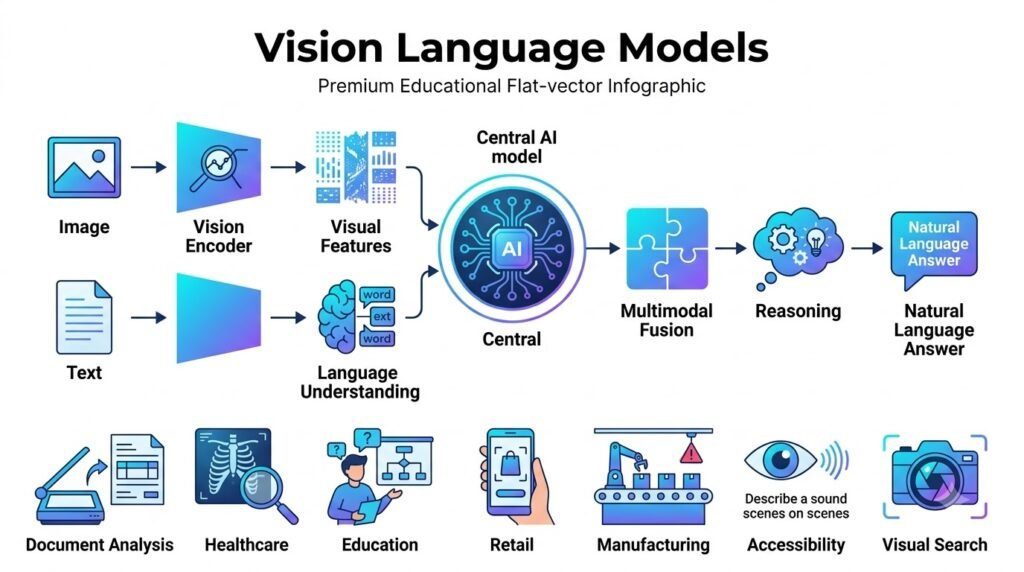
ಒಂದು simplified workflow ಹೀಗೆ:
Image Input
↓
Vision Encoder
↓
Visual Features
↓
Multimodal Fusion
↓
Language Model
↓
Reasoning / Generation
↓
Text Answer
ಇಲ್ಲಿ ಪ್ರತಿಯೊಂದು stageಗೂ ಒಂದು specific role ಇದೆ.
Step 1 — Image Input
ಮೊದಲಿಗೆ modelಗೆ image ಸಿಗುತ್ತದೆ.
ಅದು ಇರಬಹುದು:
- Photograph
- Screenshot
- Chart
- PDF page
- Product image
- Medical image
- Diagram
- Handwritten note
AI ಮೊದಲು image ಅನ್ನು computational representationಗೆ convert ಮಾಡಬೇಕು.
Step 2 — Visual Processing
ಇಲ್ಲಿ Vision Encoder imageನ visual information ಅನ್ನು process ಮಾಡುತ್ತದೆ.
Imageನಲ್ಲಿರುವ:
- objects
- shapes
- colors
- positions
- patterns
- text
- spatial relationships
ಇತ್ಯಾದಿ information ಅನ್ನು modelಗೆ useful ಆಗುವ numerical representation ಆಗಿ convert ಮಾಡಲಾಗುತ್ತದೆ.
ಇದನ್ನು ಸಾಮಾನ್ಯವಾಗಿ visual embeddings/features ಎಂದು ಕರೆಯಬಹುದು.
Step 3 — Multimodal Fusion
ಈ stageನಲ್ಲಿ visual information ಮತ್ತು text information connect ಆಗುತ್ತವೆ.
ಉದಾಹರಣೆಗೆ user ಕೇಳುತ್ತಾನೆ:
“ಈ imageನಲ್ಲಿ ಯಾವ object table ಮೇಲೆ ಇದೆ?”
ಇಲ್ಲಿ AIಗೆ ಎರಡು information sources ಇವೆ:
Visual information: imageನಲ್ಲಿ ಇರುವ objects ಮತ್ತು ಅವರ positions.
Language information: user ಕೇಳಿರುವ question.
ಈ ಎರಡನ್ನೂ combine ಮಾಡಿ relevant relationship ಹುಡುಕಬೇಕು.
OpenAI’s multimodal research provides additional context on AI systems that reason across images and text.
Step 4 — Language Understanding
ಈಗ language model visual information ಅನ್ನು language context ಜೊತೆ combine ಮಾಡುತ್ತದೆ.
ಇದರಿಂದ AIಗೆ:
“User ಏನು ಕೇಳುತ್ತಿದ್ದಾನೆ?”
ಮತ್ತು
“Imageನಲ್ಲಿ ಅದಕ್ಕೆ ಸಂಬಂಧಿಸಿದ information ಯಾವುದು?”
ಎಂಬುದನ್ನು determine ಮಾಡಲು ಸಾಧ್ಯವಾಗುತ್ತದೆ.
Step 5 — Response Generation
ಕೊನೆಯಲ್ಲಿ model ತನ್ನ understanding ಆಧಾರದ ಮೇಲೆ natural-language answer generate ಮಾಡುತ್ತದೆ.
ಉದಾಹರಣೆಗೆ:
“The laptop is placed on the table.”
ಇಲ್ಲಿ final answer simple ಆಗಿ ಕಾಣಬಹುದು. ಆದರೆ behind the scenes visual perception + language understanding + contextual reasoning combine ಆಗಿರುತ್ತದೆ.
4. Vision Encoder ಎಂದರೇನು?
Vision Encoder VLM architectureನ visual side ಅನ್ನು handle ಮಾಡುವ ಪ್ರಮುಖ component.
ಇದನ್ನು ಒಂದು ರೀತಿಯಲ್ಲಿ AIಯ “eyes” ಎಂದು imagine ಮಾಡಬಹುದು.
ಆದರೆ ಇದು human eyesನಂತೆ literally ನೋಡುವುದಿಲ್ಲ. Image ಅನ್ನು mathematical representation ಆಗಿ process ಮಾಡುತ್ತದೆ.
Simplified Flow
Image
↓
Pixels
↓
Visual Processing
↓
Features / Embeddings
↓
Language Modelಗೆ Visual Information
ಉದಾಹರಣೆಗೆ ಒಂದು bicycle photo ತೆಗೆದುಕೊಳ್ಳಿ.
Vision encoder imageನಲ್ಲಿ:
- wheels
- frame
- handlebar
- seat
- road
- background
ಹೀಗೆ ಹಲವಾರು visual patterns detect ಮಾಡಬಹುದು.
ನಂತರ ಇವುಗಳ representation ಮುಂದಿನ AI processingಗೆ ಹೋಗುತ್ತದೆ.
Important Point
Vision encoder ಕೇವಲ “ಇದು bicycle” ಎಂದು label ಕೊಡುವುದಕ್ಕಿಂತ imageನ visual structure ಅನ್ನು represent ಮಾಡುವುದು ಮುಖ್ಯ.
ಅದರ ನಂತರ language model ಆ representationನೊಂದಿಗೆ ಕೆಲಸ ಮಾಡುತ್ತದೆ.
5. Language Model ಹೇಗೆ Connect ಆಗುತ್ತದೆ?
Vision encoder ಮತ್ತು language model ಎರಡು different types of information process ಮಾಡುತ್ತವೆ.
ಒಂದು side:
Vision → Images
ಇನ್ನೊಂದು side:
Language Model → Text
ಇವೆರಡನ್ನು connect ಮಾಡಲು model architectureನಲ್ಲಿ multimodal alignment/fusion mechanisms ಬಳಸಲಾಗುತ್ತದೆ.
ಸರಳವಾಗಿ:
Image Information → Visual Representation
Question → Text Representation
ನಂತರ:
Visual + Text Representations → Joint Understanding
ಇದರಿಂದ user natural languageನಲ್ಲಿ image ಬಗ್ಗೆ questions ಕೇಳಬಹುದು.
Example
ಒಂದು supermarket shelf photo ಇದೆ.
User:
“Which product appears to have the largest package?”
ಇಲ್ಲಿ AI:
- image analyze ಮಾಡುತ್ತದೆ
- products identify ಮಾಡುತ್ತದೆ
- relative size compare ಮಾಡುತ್ತದೆ
- question context ಅರ್ಥಮಾಡಿಕೊಳ್ಳುತ್ತದೆ
- answer generate ಮಾಡುತ್ತದೆ
ಇದೇ vision + language interactionನ power.
6. Multimodal Fusion ಹೇಗೆ ನಡೆಯುತ್ತದೆ?
Multimodal fusion ಅಂದರೆ different types of information ಅನ್ನು ಒಂದೇ reasoning processನಲ್ಲಿ combine ಮಾಡುವುದು.
VLMsನಲ್ಲಿ ಇದು ಅತ್ಯಂತ important concept.
Imagine ಮಾಡಿ:
Image: ಒಂದು weather chart
Question:
“ನಾಳೆ temperature increase ಆಗುತ್ತದೆಯೇ?”
AIಗೆ chartನ visual information ಮಾತ್ರ ಸಾಕಾಗುವುದಿಲ್ಲ. User questionನ language meaning ಕೂಡ ಅರ್ಥವಾಗಬೇಕು.
ಆದ್ದರಿಂದ:
Visual Data + Language Query + Context
↓
Multimodal Understanding
↓
Answer
ಇಲ್ಲಿ AI ಎರಡು modalities ನಡುವೆ relationship ಹುಡುಕುತ್ತದೆ.
Common Modalities
| Modality | Example |
|---|---|
| Vision | Photos, images |
| Text | Questions, documents |
| Video | Recorded scenes |
| Audio | Speech/sound |
| Charts | Graphs/data visualization |
| Documents | PDFs/forms |
ಕೆಲವು advanced multimodal systems vision ಮತ್ತು language ಜೊತೆಗೆ audio/video ಮುಂತಾದ modalitiesನ್ನೂ handle ಮಾಡಬಹುದು.
7. Vision Language Models Imageನಲ್ಲಿ ಏನು ಅರ್ಥಮಾಡಿಕೊಳ್ಳಬಹುದು?
VLMsನ capability modelನ architecture, training data ಮತ್ತು task ಮೇಲೆ depend ಆಗುತ್ತದೆ. ಎಲ್ಲ VLMಗಳಿಗೂ ಒಂದೇ level of understanding ಇರುವುದಿಲ್ಲ.
ಆದರೆ modern systems ಹಲವು types of visual information handle ಮಾಡಬಹುದು.
7.1 Object Understanding
Imageನಲ್ಲಿ ಯಾವ objects ಇವೆ ಎಂದು identify ಮಾಡಬಹುದು.
ಉದಾಹರಣೆ:
Photo → Laptop + Mobile + Notebook + Coffee Cup
7.2 Scene Understanding
Objectಗಳ list ಮಾತ್ರವಲ್ಲದೆ overall sceneನ context ಕೂಡ understand ಮಾಡಲು ಪ್ರಯತ್ನಿಸಬಹುದು.
ಉದಾಹರಣೆಗೆ:
ಒಂದು classroom photoನಲ್ಲಿ:
- teacher
- students
- board
- desks
ಇವೆ.
VLM scene educational environment ಎಂದು infer ಮಾಡಬಹುದು.
7.3 Image Question Answering
User image upload ಮಾಡಿ direct question ಕೇಳಬಹುದು.
ಉದಾಹರಣೆ:
“ಈ diagramನಲ್ಲಿ arrows ಯಾವ directionಗೆ ಹೋಗುತ್ತಿವೆ?”
ಅಥವಾ:
“ಈ chartನಲ್ಲಿ highest value ಯಾವ categoryಗೆ ಇದೆ?”
ಇದು visual question answering capabilityಗೆ example.
7.4 OCR + Document Understanding
ಕೆಲವು VLM systems imagesನಲ್ಲಿ ಇರುವ text ಅನ್ನು read ಮಾಡಿ, ಅದರ surrounding layout ಮತ್ತು meaningನೊಂದಿಗೆ combine ಮಾಡಬಹುದು.
ಉದಾಹರಣೆ:
Invoice photo →
- Invoice number
- Date
- Items
- Quantity
- Price
- Total
ಇವೆಲ್ಲವನ್ನು extract/understand ಮಾಡಲು ಬಳಸಬಹುದು.
ಆದರೆ OCR accuracy, handwriting, low-resolution images ಮತ್ತು unusual layoutsನಲ್ಲಿ errors ಸಂಭವಿಸಬಹುದು.
8. Real-World Examples
VLMs theoretical technology ಮಾತ್ರ ಅಲ್ಲ. Visual information important ಆಗಿರುವ ಹಲವು real-world workflowsನಲ್ಲಿ ಅವು useful ಆಗಬಹುದು.
Example 1 — Shopping
ಒಬ್ಬ customer shoe photo upload ಮಾಡಿ ಕೇಳಬಹುದು:
“ಈ shoes casual wearಗೆ suitable ಆಗುತ್ತವೆಯೇ?”
System imageನ visual characteristics ನೋಡಿ contextual answer ನೀಡಬಹುದು.
Example 2 — Education
Student ಒಂದು textbook diagram upload ಮಾಡಿ:
“ಈ diagramನ process ಅನ್ನು simple Kannadaನಲ್ಲಿ explain ಮಾಡಿ.”
ಎಂದು ಕೇಳಬಹುದು.
VLM visual structure identify ಮಾಡಿ, ನಂತರ explanation ಅನ್ನು requested languageನಲ್ಲಿ generate ಮಾಡಬಹುದು.
ಇದು AI-based visual learningಗೆ useful application.
Example 3 — Document Processing
ಒಂದು companyಗೆ thousands of scanned documents ಇದ್ದರೆ, VLM-based systems documentsನ visual layout ಮತ್ತು text ಎರಡನ್ನೂ analyze ಮಾಡಲು ಬಳಸಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Document → Classification → Information Extraction → Summary
Manual processingಗಿಂತ automation ಸಾಧ್ಯವಾಗುವ area ಇದು.
9. Vision Language Models in Education
Educationನಲ್ಲಿ VLMs ಬಹಳ interesting use case ಹೊಂದಿವೆ.
ಒಂದು studentಗೆ physics diagram ಅರ್ಥವಾಗುತ್ತಿಲ್ಲ ಎಂದು imagine ಮಾಡಿ.
ಅವನು diagram photo upload ಮಾಡಿ:
“ಈ diagramನಲ್ಲಿ force ಯಾವ directionಗೆ ಇದೆ? Kannadaನಲ್ಲಿ explain ಮಾಡಿ.”
ಎಂದು ಕೇಳಬಹುದು.
VLM visual contentನೊಂದಿಗೆ question ಅನ್ನು combine ಮಾಡಿ explanation ನೀಡಬಹುದು.
Possible Educational Applications
- Textbook diagram explanation
- Mathematics graphs
- Physics diagrams
- Biology illustrations
- Geography maps
- Historical images
- Handwritten notes
- Presentation slides
- Visual question answering
ಇದರಿಂದ learning ಹೆಚ್ಚು interactive ಮತ್ತು personalized ಆಗಬಹುದು.
ಆದರೆ educational answers ಅನ್ನು blindly trust ಮಾಡಬಾರದು. Model visual detail ಅನ್ನು ತಪ್ಪಾಗಿ interpret ಮಾಡಿದರೆ answer ಕೂಡ ತಪ್ಪಾಗಬಹುದು.
10. VLMs in Business and Documents
Business environmentನಲ್ಲಿ ದೊಡ್ಡ amount of information text ರೂಪದಲ್ಲೇ ಇರೋದಿಲ್ಲ.
ಬಹಳಷ್ಟು data:
- invoices
- receipts
- forms
- charts
- scanned documents
- product photographs
- reports
- dashboards
ರೂಪದಲ್ಲಿರುತ್ತದೆ.
Traditional text-only AIಗೆ ಈ informationನ full context ಪಡೆಯಲು image/document processing pipeline ಬೇಕಾಗಬಹುದು.
VLMs ಈ process ಅನ್ನು ಹೆಚ್ಚು integrated ಆಗಿ handle ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
Example: Invoice Processing
Invoice Image
↓
Visual + Text Understanding
↓
Vendor Detection
↓
Invoice Number
↓
Date
↓
Line Items
↓
Total Amount
↓
Structured Business Data
ಇದರಿಂದ finance, accounting ಮತ್ತು operations workflowsನಲ್ಲಿ automation ಸಾಧ್ಯ.
11. Vision Language Models in Manufacturing and Robotics
Manufacturingನಲ್ಲಿ AIಗೆ physical world ಅರ್ಥಮಾಡಿಕೊಳ್ಳುವುದು ಬಹಳ important.
ಒಂದು factory floorನಲ್ಲಿ camera systems continuously visual information capture ಮಾಡಬಹುದು.
VLM-based systems potential applicationsನಲ್ಲಿ:
- product inspection
- visual quality checking
- equipment monitoring
- assembly verification
- safety observation
- warehouse understanding
ಮುಂತಾದ tasksಗೆ ಬಳಸಬಹುದು.
Roboticsನಲ್ಲಿ
Robot ಒಂದು environmentನಲ್ಲಿ move ಮಾಡುವಾಗ ಅದು:
See → Understand → Decide → Act
ಎಂಬ loop follow ಮಾಡಬೇಕಾಗುತ್ತದೆ.
VLMsನ visual-language understanding robotಗೆ human instructions ಮತ್ತು visual environment ನಡುವೆ connection ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
ಉದಾಹರಣೆ:
“Table ಮೇಲಿರುವ blue box ತೆಗೆದುಕೊಂಡು shelfನಲ್ಲಿ ಇಡು.”
ಇಲ್ಲಿ systemಗೆ:
- “blue box” ಯಾವ object?
- “table” ಯಾವ location?
- “shelf” ಎಲ್ಲಿದೆ?
- instructionನಲ್ಲಿ object-location relationship ಏನು?
ಎಂಬುದನ್ನು connect ಮಾಡಬೇಕಾಗುತ್ತದೆ.
ಇದು roboticsನಲ್ಲಿ language-guided visual understandingಗೆ ಒಂದು important direction.
12. Vision Language Models — Major Benefits
VLMsನ biggest advantage ಎಂದರೆ different information types ಅನ್ನು ಒಂದೇ AI workflowನಲ್ಲಿ combine ಮಾಡುವುದು.
1. Better Visual Understanding
Imagesನಲ್ಲಿ ಇರುವ information ಅನ್ನು language interaction ಜೊತೆ ಬಳಸಬಹುದು.
2. Natural Interaction
Userಗೆ complicated computer-vision commands ಕಲಿಯಬೇಕಾಗಿಲ್ಲ.
ಸರಳವಾಗಿ:
“ಈ imageನಲ್ಲಿ ಏನಿದೆ?”
ಎಂದು ಕೇಳಬಹುದು.
3. Document Automation
Visual documentsನಿಂದ useful information extract ಮಾಡುವ workflows simplify ಆಗಬಹುದು.
4. Accessibility
Visual information ಅನ್ನು text-based descriptionsಗೆ convert ಮಾಡುವ applications ಸಾಧ್ಯ.
5. Business Automation
Manual image/document inspection ಕಡಿಮೆ ಮಾಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
6. Human-AI Interaction
Human instructions ಮತ್ತು visual environment ನಡುವೆ bridge ಆಗಿ ಕೆಲಸ ಮಾಡಬಹುದು.
13. VLMsನ Limitations ಕೂಡ Important
Technology powerful ಆದರೂ Vision Language Models perfect ಅಲ್ಲ.
AI answer confident ಆಗಿ ಹೇಳಿದರೂ ಅದು necessarily correct ಅಂತ ಅರ್ಥವಲ್ಲ.
13.1 Hallucination
Model imageನಲ್ಲಿ ಇಲ್ಲದ information ಅನ್ನು ಕೂಡ generate ಮಾಡಬಹುದು.
ಉದಾಹರಣೆಗೆ imageನಲ್ಲಿ object unclear ಇದ್ದರೂ AI confidently ಅದರ identity ಹೇಳಬಹುದು.
13.2 Small Details
Very small objects, blurry images ಅಥವಾ low-resolution textಗಳನ್ನು correctly interpret ಮಾಡುವುದು difficult ಆಗಬಹುದು.
13.3 Spatial Reasoning
Objects ನಡುವಿನ exact distance, depth, orientation ಅಥವಾ position ಅನ್ನು accurately understand ಮಾಡುವುದು challenging ಆಗಿರಬಹುದು.
13.4 OCR Errors
Blurred documents, handwriting, unusual fonts ಅಥವಾ poor lighting ಇದ್ದಾಗ text readingನಲ್ಲಿ mistakes ಆಗಬಹುದು.
13.5 Bias
Training dataನಲ್ಲಿ bias ಇದ್ದರೆ visual interpretation ಅಥವಾ generated responseನಲ್ಲೂ bias reflect ಆಗಬಹುದು.
13.6 Privacy
Imagesನಲ್ಲಿ:
- faces
- IDs
- addresses
- financial documents
- medical information
ಹಾಗೂ sensitive information ಇರಬಹುದು.
ಆದ್ದರಿಂದ business ಅಥವಾ personal images AI systemsಗೆ upload ಮಾಡುವಾಗ privacy, data retention ಮತ್ತು security policies carefully consider ಮಾಡಬೇಕು.
Vision Language Models ಅನ್ನು ಹೇಗೆ Think ಮಾಡಬೇಕು?
ಒಂದು simple mental model ನೆನಪಿಟ್ಟುಕೊಳ್ಳಿ:
Traditional AI: “ನಾನು text ಅರ್ಥಮಾಡಿಕೊಳ್ಳುತ್ತೇನೆ.”
Computer Vision: “ನಾನು visual patterns analyze ಮಾಡುತ್ತೇನೆ.”
Vision Language Model: “ನಾನು visual information ಅನ್ನು language context ಜೊತೆ connect ಮಾಡಿ ಅರ್ಥಮಾಡಿಕೊಳ್ಳಲು ಪ್ರಯತ್ನಿಸುತ್ತೇನೆ.”
ಇದೇ VLM conceptನ core idea.
A Simple VLM Workflow
📷 Image
↓
👁️ Vision Encoder
Imageನ visual features capture ಮಾಡುತ್ತದೆ
↓
🔗 Multimodal Fusion
Image + Question ಅನ್ನು connect ಮಾಡುತ್ತದೆ
↓
🧠 Language Model
Context ಮತ್ತು meaning process ಮಾಡುತ್ತದೆ
↓
💡 Reasoning
Relevant information identify ಮಾಡುತ್ತದೆ
↓
💬 Natural Language Answer
Userಗೆ understandable response ಕೊಡುತ್ತದೆ
Did You Know?
ಒಂದು imageನಲ್ಲಿರುವ objects identify ಮಾಡುವುದು ಮಾತ್ರ VLM technologyಯ main goal ಅಲ್ಲ. Visual information ಮತ್ತು language instructions ನಡುವೆ meaningful connection ನಿರ್ಮಿಸುವುದು ಅದರ ಹೆಚ್ಚು powerful capabilityಗಳಲ್ಲಿ ಒಂದು.
ಅದಕ್ಕಾಗಿಯೇ VLMs future AI assistants, document automation, education ಮತ್ತು roboticsನಲ್ಲಿ important technology ಆಗುತ್ತಿವೆ.
Future, Applications, Benefits, Challenges & FAQs
Part 2ರಲ್ಲಿ ನಾವು Vision Language Models (VLMs) ಹೇಗೆ images ಮತ್ತು text ಅನ್ನು ಒಟ್ಟಿಗೆ process ಮಾಡುತ್ತವೆ ಅನ್ನೋದನ್ನು ನೋಡಿದ್ದೇವೆ. ಈಗ Part 3ನಲ್ಲಿ ಇದರ real-world impact, future possibilities, business value ಮತ್ತು limitations ಅನ್ನು ನೋಡೋಣ.
14. Vision Language Models Futureನಲ್ಲಿ ಏಕೆ Important?
ಇಂದಿನ AI systemsನಲ್ಲಿ ಒಂದು ದೊಡ್ಡ shift ನಡೆಯುತ್ತಿದೆ.
ಹಿಂದೆ AI ಜೊತೆ interaction ಮುಖ್ಯವಾಗಿ:
Type → Read → Answer
ಇತ್ತು.
ಆದರೆ ಈಗ interaction ಹೆಚ್ಚು:
See → Understand → Reason → Respond → Act
ಎಂಬ directionಗೆ ಹೋಗುತ್ತಿದೆ.
ಅಂದರೆ AI ಕೇವಲ ನಾವು type ಮಾಡುವ words ಅನ್ನು ಮಾತ್ರ understand ಮಾಡುವುದು ಅಲ್ಲ; ನಾವು ತೋರಿಸುವ image, document, screen, chart ಅಥವಾ physical environmentನ information ಕೂಡ ಅರ್ಥಮಾಡಿಕೊಳ್ಳುವ ಸಾಮರ್ಥ್ಯ ಪಡೆಯುತ್ತಿದೆ.
ಇದರಿಂದ future AI assistants ಹೆಚ್ಚು natural ಆಗಬಹುದು.
ಒಂದು simple example
ನೀವು ಒಂದು machine photo ತೆಗೆದು AIಗೆ:
“ಇಲ್ಲಿ problem ಏನಿರಬಹುದು?”
ಎಂದು ಕೇಳುತ್ತೀರಿ.
AI visual information ಅನ್ನು analyze ಮಾಡಿ possible issueಗಳನ್ನು explain ಮಾಡಬಹುದು.
ಆದರೆ ಇಲ್ಲಿ ಒಂದು important point ಇದೆ: AI ನೀಡುವ suggestion ಅನ್ನು expert inspectionಗೆ replacement ಎಂದು ಪರಿಗಣಿಸಬಾರದು, ವಿಶೇಷವಾಗಿ safety-critical environmentsನಲ್ಲಿ.
15. VLMs + AI Agents
Futureನಲ್ಲಿ Vision Language Models ಮತ್ತು AI Agents ಒಂದಾಗಿ ಕೆಲಸ ಮಾಡುವ ಸಾಧ್ಯತೆ ಬಹಳ important.
ಒಂದು AI agentಗೆ visual understanding ಬಂದರೆ ಅದು physical ಅಥವಾ digital environmentನಲ್ಲಿ ಹೆಚ್ಚು context-aware ಆಗಬಹುದು.
Example
ಒಂದು warehouseನಲ್ಲಿ:
Camera → VLM → AI Agent → Decision → Action
Camera environment ನೋಡುತ್ತದೆ.
VLM:
- products
- shelves
- labels
- obstacles
ಅನ್ನು understand ಮಾಡಲು ಸಹಾಯ ಮಾಡುತ್ತದೆ.
AI agent ನಂತರ task instruction ಜೊತೆ combine ಮಾಡಿ next action decide ಮಾಡಬಹುದು.
ಉದಾಹರಣೆಗೆ:
“Shelf B-12ನಲ್ಲಿ missing package ಇದೆಯೇ check ಮಾಡಿ.”
ಇಲ್ಲಿ AIಗೆ text instruction ಮಾತ್ರ ಸಾಕಾಗುವುದಿಲ್ಲ. Shelf ಮತ್ತು packageನ visual context ಕೂಡ ಬೇಕಾಗುತ್ತದೆ.
ಇದೇ multimodal AI ಮತ್ತು agentic AI ಒಂದಾಗುವ ಪ್ರಮುಖ direction.
16. VLMs + Robotics
Roboticsನಲ್ಲಿ ಒಂದು robotಗೆ physical world understand ಮಾಡುವುದು ಅತ್ಯಂತ important.
Traditional robot systemsನಲ್ಲಿ tasks highly structured ಆಗಿರಬಹುದು.
ಆದರೆ future robots ಹೆಚ್ಚು flexible ಆಗಬೇಕಾದರೆ:
Vision + Language + Reasoning + Action
ಎಲ್ಲವೂ combine ಆಗಬೇಕು.
Example
ಒಬ್ಬ worker ಹೇಳುತ್ತಾನೆ:
“ಈ table ಮೇಲಿರುವ empty box ತೆಗೆದು recycling areaಗೆ ಇಡು.”
Robotಗೆ:
- table ಯಾವುದು?
- box ಯಾವುದು?
- empty box ಯಾವುದು?
- recycling area ಎಲ್ಲಿದೆ?
- object ಅನ್ನು safely ಹೇಗೆ move ಮಾಡಬೇಕು?
ಎಂಬ context ಅರ್ಥವಾಗಬೇಕು.
ಇಲ್ಲಿ VLM visual understanding ನೀಡಬಹುದು, ಆದರೆ actual physical actionಗೆ robotics control systems, sensors ಮತ್ತು safety mechanisms ಕೂಡ ಅಗತ್ಯ.
NVIDIA’s robotics platform shows how vision AI and foundation models are being integrated into physical AI and robotics.
17. VLMs in Healthcare
Healthcareನಲ್ಲಿ medical images ಮತ್ತು clinical information ಎರಡೂ important.
Future AI systemsನಲ್ಲಿ:
Medical Image + Clinical Text + Patient Context
ಒಟ್ಟಿಗೆ analyze ಮಾಡುವ multimodal approaches ಹೆಚ್ಚು useful ಆಗಬಹುದು.
Possible applications:
- Medical image analysis
- Radiology assistance
- Medical document understanding
- Patient information summarization
- Visual clinical decision support
ಆದರೆ ಇದು high-stakes domain.
ಹೀಗಾಗಿ VLM-generated output ಅನ್ನು doctor ಅಥವಾ qualified healthcare professionalನ judgmentಗೆ substitute ಮಾಡುವುದು ಸರಿಯಲ್ಲ.
AI ತಪ್ಪಾಗಿ image interpret ಮಾಡಿದರೆ ಅದರ ಪರಿಣಾಮ serious ಆಗಬಹುದು.
18. VLMs in Accessibility
ಇದು VLM technologyಯ socially valuable applicationsನಲ್ಲಿ ಒಂದು.
Visual information ಅನ್ನು directly access ಮಾಡಲು ಸಾಧ್ಯವಾಗದ usersಗೆ AI:
- image descriptions
- document explanations
- scene descriptions
- visual question answering
ಮುಂತಾದ capabilities ನೀಡಬಹುದು.
ಉದಾಹರಣೆಗೆ, ಒಬ್ಬ user ಒಂದು photo upload ಮಾಡಿ:
“ಈ imageನಲ್ಲಿ ಏನಿದೆ ಎಂದು Kannadaನಲ್ಲಿ ಹೇಳಿ.”
ಎಂದು ಕೇಳಬಹುದು.
AI imageನ relevant visual information ಅನ್ನು natural languageನಲ್ಲಿ describe ಮಾಡಬಹುದು.
ಇದರಿಂದ visual informationಗೆ alternative language-based access ಸಿಗಬಹುದು.
19. VLMs in Customer Support
Customer supportನಲ್ಲಿ users ಹಲವಾರು ಬಾರಿ problem ಅನ್ನು textನಲ್ಲಿ explain ಮಾಡುವುದಕ್ಕಿಂತ photo ಕಳುಹಿಸುವುದು ಸುಲಭ.
ಉದಾಹರಣೆ:
ಒಬ್ಬ customer ಒಂದು productನ damaged-part photo upload ಮಾಡುತ್ತಾನೆ.
ಅದರ ಜೊತೆ:
“ಈ partನಲ್ಲಿ ಏನು problem ಇದೆ?”
ಎಂದು ಕೇಳುತ್ತಾನೆ.
VLM-based support system imageನ visual information ಅನ್ನು inspect ಮಾಡಿ initial guidance ನೀಡಲು ಸಹಾಯ ಮಾಡಬಹುದು.
Possible Workflow
Customer Photo
↓
Visual Analysis
↓
Product / Issue Context
↓
Knowledge Base
↓
AI Response
↓
Human Escalation if Required
ಇಲ್ಲಿ VLM ಮಾತ್ರ ಸಾಕಾಗುವುದಿಲ್ಲ. Product knowledge base ಮತ್ತು business rules ಕೂಡ connect ಆಗಬೇಕಾಗಬಹುದು.
20. VLMs in E-Commerce
E-commerceನಲ್ಲಿ product images ಬಹಳ important.
VLM technology ಬಳಸಿ:
- Product description generation
- Image-based product search
- Product comparison
- Visual categorization
- Attribute extraction
- Catalog enrichment
ಮುಂತಾದ workflows automate ಮಾಡಬಹುದು.
ಉದಾಹರಣೆಗೆ:
Product Photo → AI Understanding → Product Attributes → Description
ಒಂದು sellerಗೆ hundreds of products ಇದ್ದರೆ manual catalog creation workload ಕಡಿಮೆಯಾಗಬಹುದು.
ಆದರೆ generated product descriptionsನಲ್ಲಿ incorrect specifications ಅಥವಾ invented attributes ಬರದಂತೆ human review ಅಥವಾ validation ಅಗತ್ಯ.
21. VLMs ಮತ್ತು Search Technology
Future search systemsನಲ್ಲಿ users keywords ಮಾತ್ರ type ಮಾಡುವುದಕ್ಕಿಂತ images ಮತ್ತು natural language ಎರಡನ್ನೂ combine ಮಾಡಬಹುದು.
ಉದಾಹರಣೆಗೆ:
ನೀವು ಒಂದು chair photo upload ಮಾಡಿ:
“ಇದೇ styleನಲ್ಲಿ ₹10,000 ಒಳಗೆ ಇರುವ chairs ಹುಡುಕಿ.”
ಇಲ್ಲಿ search systemಗೆ:
Image Understanding + Text Query + Product Search
ಮೂರನ್ನೂ combine ಮಾಡಬೇಕು.
ಇದು traditional keyword searchಗಿಂತ ಹೆಚ್ಚು natural search experience ಕೊಡಬಹುದು.
22. VLMsನ Business Value
Business perspectiveನಲ್ಲಿ technology powerful ಆಗೋದು ಅದು real operational problem solve ಮಾಡಿದಾಗ.
VLMsನ value ಹೆಚ್ಚಾಗುವ ಕೆಲವು areas:
| Business Area | VLM Use |
|---|---|
| Documents | Information extraction |
| Manufacturing | Visual inspection |
| Retail | Product understanding |
| E-commerce | Image search |
| Education | Diagram explanation |
| Customer Support | Photo-based troubleshooting |
| Logistics | Package/warehouse understanding |
| Accessibility | Image descriptions |
| Robotics | Visual-language instructions |
ಇಲ್ಲಿ main benefit ಕೇವಲ “AI can see” ಅಲ್ಲ.
AI can connect what it sees with what people ask.
ಇದೇ business workflowsನಲ್ಲಿ VLMsನ real value.
23. VLMsನಲ್ಲಿ Accuracy ಯಾಕೆ Important?
AI imageನ ಬಗ್ಗೆ answer ಕೊಟ್ಟಾಗ ಅದು fluent ಆಗಿರಬಹುದು.
ಆದರೆ fluent answer = correct answer ಅಂತ ಅಲ್ಲ.
ಇದು VLM deploymentನಲ್ಲಿ ಬಹಳ important consideration.
ಉದಾಹರಣೆಗೆ:
ಒಂದು invoiceನಲ್ಲಿ total ₹18,500 ಇದೆ ಎಂದು imagine ಮಾಡಿ.
AI ತಪ್ಪಾಗಿ ₹13,500 ಎಂದು read ಮಾಡಿದರೆ financial workflowನಲ್ಲಿ problem ಆಗಬಹುದು.
ಅದೇ ರೀತಿ:
ಒಂದು factory safety imageನಲ್ಲಿ dangerous condition ಇದೆ. AI ಅದನ್ನು miss ಮಾಡಿದರೆ safety risk ಉಂಟಾಗಬಹುದು.
ಆದ್ದರಿಂದ business implementationನಲ್ಲಿ:
AI Output → Validation → Human Review → Action
ಎಂಬ controlled workflow ಹೆಚ್ಚು reliable.
24. VLMsನಲ್ಲಿ Privacy ಮತ್ತು Security
Imagesನಲ್ಲಿ textಗಿಂತಲೂ ಹೆಚ್ಚು sensitive information ಇರಬಹುದು.
ಒಂದು photoನಲ್ಲಿ accidentally:
- Aadhaar/ID information
- phone number
- address
- financial details
- employee information
- medical records
- faces
ಕಾಣಿಸಬಹುದು.
ಆದ್ದರಿಂದ VLM deploymentನಲ್ಲಿ data privacy ಮತ್ತು security ಅನ್ನು ಆರಂಭದಲ್ಲೇ consider ಮಾಡಬೇಕು.
Business users ವಿಶೇಷವಾಗಿ:
- data storage policy
- access controls
- retention
- encryption
- model provider policies
- sensitive-data handling
ಇವುಗಳನ್ನು ಪರಿಶೀಲಿಸಬೇಕು.
“AIಗೆ image upload ಮಾಡಿದೆ” ಅಷ್ಟೇ simple ವಿಷಯ ಅಲ್ಲ; imageನಲ್ಲಿ ಯಾವ data ಇದೆ ಅನ್ನೋದು ಕೂಡ equally important.
25. VLMsನ Future Direction
ಮುಂದಿನ ವರ್ಷಗಳಲ್ಲಿ VLM development ಹಲವು directionsನಲ್ಲಿ ಮುಂದುವರಿಯಬಹುದು.
1. Better Visual Reasoning
AI complex diagrams, charts ಮತ್ತು scenes ಅನ್ನು ಇನ್ನಷ್ಟು accurately understand ಮಾಡುವ direction.
2. Longer Context
ಒಂದು single image ಬದಲಾಗಿ multiple images, documents ಮತ್ತು conversationsನ context combine ಮಾಡುವುದು.
3. Video Understanding
ಒಂದು static image ಮಾತ್ರವಲ್ಲದೆ events ಮತ್ತು actions over time understand ಮಾಡುವುದು.
4. Real-Time Vision
Camera feedsನಿಂದ real-time visual understanding.
5. Smaller Efficient Models
Cloudನಲ್ಲಿ ಮಾತ್ರ ಅಲ್ಲದೆ edge devicesನಲ್ಲಿ run ಆಗುವ compact models.
6. Better Agent Integration
VLM + AI Agent + Tools + Robotics combination.
NVIDIA Cosmos provides a current example of vision-language reasoning being applied to physical AI.
26. Vision Language Models vs Multimodal AI
ಈ ಎರಡು terms ಒಂದೇ ರೀತಿ ಕಾಣಿಸಿದರೂ scopeನಲ್ಲಿ difference ಇದೆ.
Vision Language Model ಮುಖ್ಯವಾಗಿ visual information ಮತ್ತು language ನಡುವಿನ interaction ಮೇಲೆ focus ಮಾಡುತ್ತದೆ.
Multimodal AI ಇನ್ನಷ್ಟು broad concept.
ಅದು:
- Text
- Image
- Audio
- Video
- Speech
- Other data types
ಒಟ್ಟಿಗೆ process ಮಾಡಬಹುದು.
ಅಂದರೆ:
VLM ⊂ Multimodal AI
ಎಂದು simplified ಆಗಿ think ಮಾಡಬಹುದು.
ಎಲ್ಲ VLMs multimodal AI ecosystemನ ಭಾಗವಾಗಬಹುದು, ಆದರೆ ಎಲ್ಲ multimodal systems ಅನ್ನು VLM ಎಂದು ಕರೆಯುವುದು ಸರಿಯಾಗುವುದಿಲ್ಲ.
27. Futureನಲ್ಲಿ VLMs ನಮ್ಮ Daily Life ಅನ್ನು ಹೇಗೆ ಬದಲಾಯಿಸಬಹುದು?
ನೀವು camera-based AI assistant ಬಳಸಿ:
“ನನ್ನ ಮುಂದೆ ಇರುವ machineನಲ್ಲಿ ಈ button ಯಾವುದು?”
ಎಂದು ಕೇಳಬಹುದು.
ಅಥವಾ:
“ಈ documentನಲ್ಲಿ signature ಬೇಕಾದ ಜಾಗ ತೋರಿಸು.”
ಅಥವಾ:
“ಈ plantಗೆ sunlight ಸಾಕಾಗುತ್ತಿದೆಯೇ?”
ಹೀಗೆ AI interaction text-only interfaceನಿಂದ visual interfaceಗೆ expand ಆಗಬಹುದು.
ಇದು smartphones, smart glasses, robots, vehicles ಮತ್ತು workplace systemsನಲ್ಲಿ ದೊಡ್ಡ change ತರಬಹುದು.
Key Takeaways
🔹 1. VLMs image + language ಅನ್ನು connect ಮಾಡುತ್ತವೆ
Vision Language Models visual information ಮತ್ತು natural language ಅನ್ನು combine ಮಾಡಿ context ಅರ್ಥಮಾಡಿಕೊಳ್ಳಲು ಪ್ರಯತ್ನಿಸುತ್ತವೆ.
🔹 2. ಇದು simple image recognitionಗಿಂತ advanced
Object identify ಮಾಡುವುದರ ಜೊತೆಗೆ user question ಮತ್ತು visual context ನಡುವೆ relationship ಹುಡುಕಬಹುದು.
🔹 3. Vision Encoder ಪ್ರಮುಖ component
ಇದು imageನ visual features ಅನ್ನು AI process ಮಾಡಬಹುದಾದ representationಗೆ convert ಮಾಡುತ್ತದೆ.
🔹 4. Multimodal Fusion core technology
Image information ಮತ್ತು language information combine ಆಗುವ ಮೂಲಕ richer understanding ಸಾಧ್ಯ.
🔹 5. ಹಲವು industriesನಲ್ಲಿ applications ಇವೆ
Education, healthcare, manufacturing, robotics, e-commerce, documents ಮತ್ತು customer support ಪ್ರಮುಖ areas.
🔹 6. Accuracy ಇನ್ನೂ challenge
Hallucination, OCR mistakes, spatial reasoning ಮತ್ತು ambiguous images ಕಾರಣದಿಂದ AI output ತಪ್ಪಾಗಬಹುದು.
🔹 7. Privacy equally important
Imagesನಲ್ಲಿ sensitive personal ಅಥವಾ business information ಇರಬಹುದು. ಆದ್ದರಿಂದ secure handling ಅಗತ್ಯ.
🔹 8. Future AI ಹೆಚ್ಚು visual ಆಗಬಹುದು
Text-only AIಯಿಂದ See → Understand → Reason → Act systems ಕಡೆക്ക് evolution ನಡೆಯುತ್ತಿದೆ.
In This Article You Learned
ಈ articleನಲ್ಲಿ ನಾವು Vision Language Models ಬಗ್ಗೆ step-by-step ಆಗಿ ಕಲಿತಿದ್ದೇವೆ.
ನಾವು:
- VLM ಎಂದರೇನು ಎಂದು ತಿಳಿದುಕೊಂಡೆವು
- Traditional Computer Vision ಮತ್ತು VLM ನಡುವಿನ difference ನೋಡಿದೆವು
- VLM architecture ಹೇಗೆ ಕೆಲಸ ಮಾಡುತ್ತದೆ ಎಂದು ಅರ್ಥಮಾಡಿಕೊಂಡೆವು
- Vision Encoderನ role ತಿಳಿದುಕೊಂಡೆವು
- Language Model ಜೊತೆ visual information ಹೇಗೆ connect ಆಗುತ್ತದೆ ಎಂದು ನೋಡಿದೆವು
- Multimodal Fusion concept ಕಲಿತೆವು
- Image understanding ಮತ್ತು document processing applications ನೋಡಿದೆವು
- Education, business, robotics, healthcare ಮತ್ತು e-commerce use cases ಪರಿಶೀಲಿಸಿದೆವು
- VLMsನ limitations ಮತ್ತು privacy risks ಅರ್ಥಮಾಡಿಕೊಂಡೆವು
- Futureನಲ್ಲಿ VLM + AI Agents + Robotics ಹೇಗೆ combine ಆಗಬಹುದು ಎಂದು ನೋಡಿದೆವು
Final Article Summary
Vision Language Models AIಗೆ visual world ಮತ್ತು human language ನಡುವೆ ಒಂದು powerful bridge ನಿರ್ಮಿಸುತ್ತವೆ.
ಸರಳವಾಗಿ ಹೇಳುವುದಾದರೆ:
AI ಕೇವಲ “ಓದುವುದು” ಮಾತ್ರವಲ್ಲ — ಅದು “ನೋಡುವುದು ಮತ್ತು ಅದನ್ನು language contextನಲ್ಲಿ ಅರ್ಥಮಾಡಿಕೊಳ್ಳುವುದು” ಕಡೆಗೆ ಸಾಗುತ್ತಿದೆ.
ಒಂದು image, document, chart ಅಥವಾ sceneನ information ಅನ್ನು user ಕೇಳುವ question ಜೊತೆ combine ಮಾಡಿ meaningful response ನೀಡುವ capability VLMsನ ಪ್ರಮುಖ strength.
ಆದರೆ technology ಇನ್ನೂ perfect ಅಲ್ಲ. Hallucination, accuracy, privacy, bias ಮತ್ತು reasoning limitations ಇರುವುದರಿಂದ critical applicationsನಲ್ಲಿ human validation ಬಹಳ ಮುಖ್ಯ.
Futureನಲ್ಲಿ VLMs AI assistants, search engines, robotics, smart devices ಮತ್ತು enterprise automationಗಳಲ್ಲಿ ಇನ್ನಷ್ಟು ದೊಡ್ಡ role play ಮಾಡುವ ಸಾಧ್ಯತೆ ಇದೆ.